Settings
Overview
Loading records or data into the Matchbook Portal for processing requires essential configuration settings to be established by the organization’s Admin. These configurations are crucial as they determine the data processing framework, aligning it with the specific business rules and needs of the organization. Properly setting these configurations ensures that the data will be handled correctly and efficiently, reflecting the unique operational requirements and objectives of the business.
The configuration process is a preliminary step that lays the foundation for seamless data import and export processing. By carefully defining these settings, the admin ensures that the Matchbook Portal operates in harmony with the organization’s standards and expectations. Once the configuration steps are completed, users can confidently proceed to import their data into the portal, knowing that it will be processed accurately and in accordance with the predefined business rules.
In the Settings section, admins can configure general settings for Matchbook AI’s operation across all users. There are three primary categories of configurations under settings.
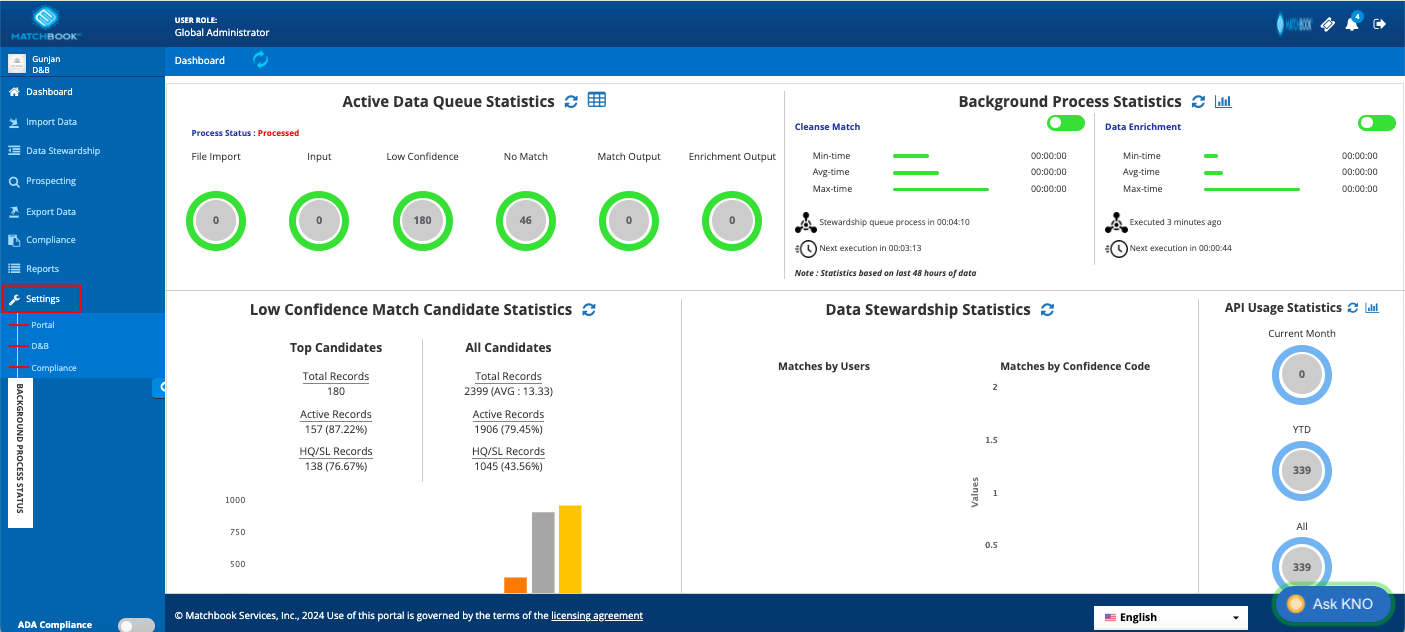
Settings-Navigation
Settings section has been discussed in detail in further section of the document.
Portal
This provides an overview of system configurations, security protocols, data management, and organizational details. The portal tab features six sections
General
Security
Common
Data Integration
Company Knowledge Base
About Us
The General section will become accessible only after the client deploys instances. This area provides essential settings and configurations for managing and customizing the deployed environment, ensuring that all operational parameters are aligned with the client’s requirements.
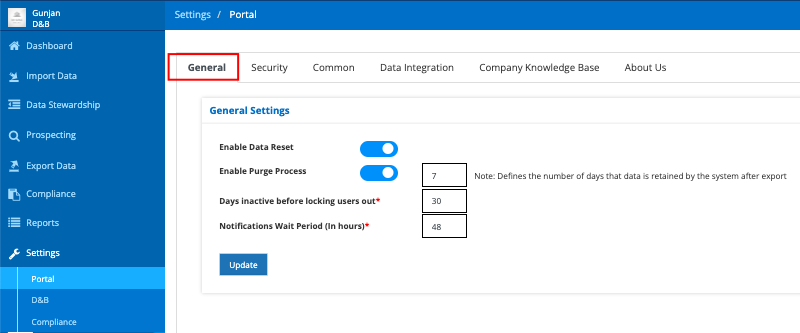
Settings>>Portal>>General
Enable Data Reset: The Enable Data Reset feature allows users with the appropriate privileges to remove all data from their instance.
For example, if you have 49 records: comprising of no match, enrichment, and low confidence data
Go to D&B settings, click on the Reset DnB Data button

Settings-Reset DnB Data
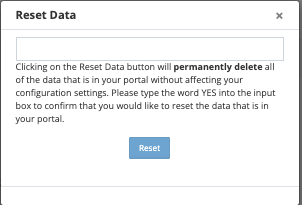
Settings-Confirm Reset DnB Data
Type Yes and click on Reset will clear all data, effectively initiating the data reset process.
Enable Purge Process: The Enable Purge Process feature facilitates the removal of individual or problematic records from the system. It also specifies the number of days data is retained after export, meaning how long it remains in Matchbook.
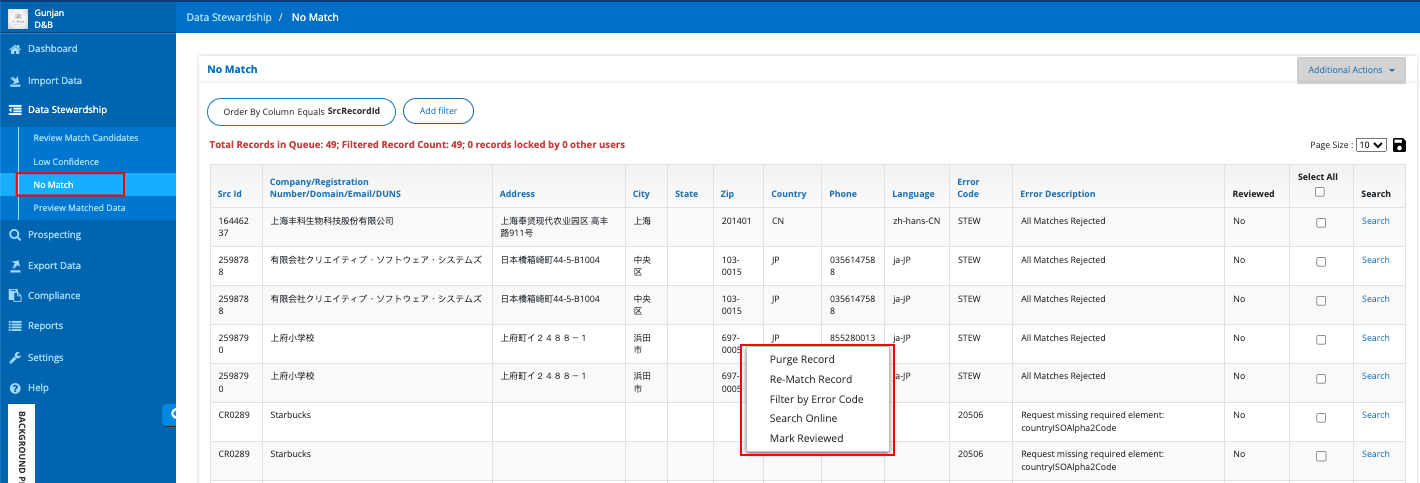
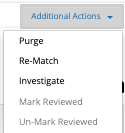
To purge a record, from the left-hand side menu go to Data Stewardship, select No Match queue.
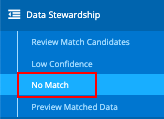
Data Stewardship-No Match
Settings-Confirm Reset DnB Data
Settings-Confirm Purge record
Additional Actions
Days Inactive Before Locking Users Out: This customizable setting defines the number of days a user can remain inactive before their account is locked. If a user does not log in within the specified timeframe, they will need to request a re-login, which requires verifying their identity with a verification code.
Notifications Wait Period (In hours): Enter the wait period to trigger notifications in hours.
Click on the Update button to update all the settings.
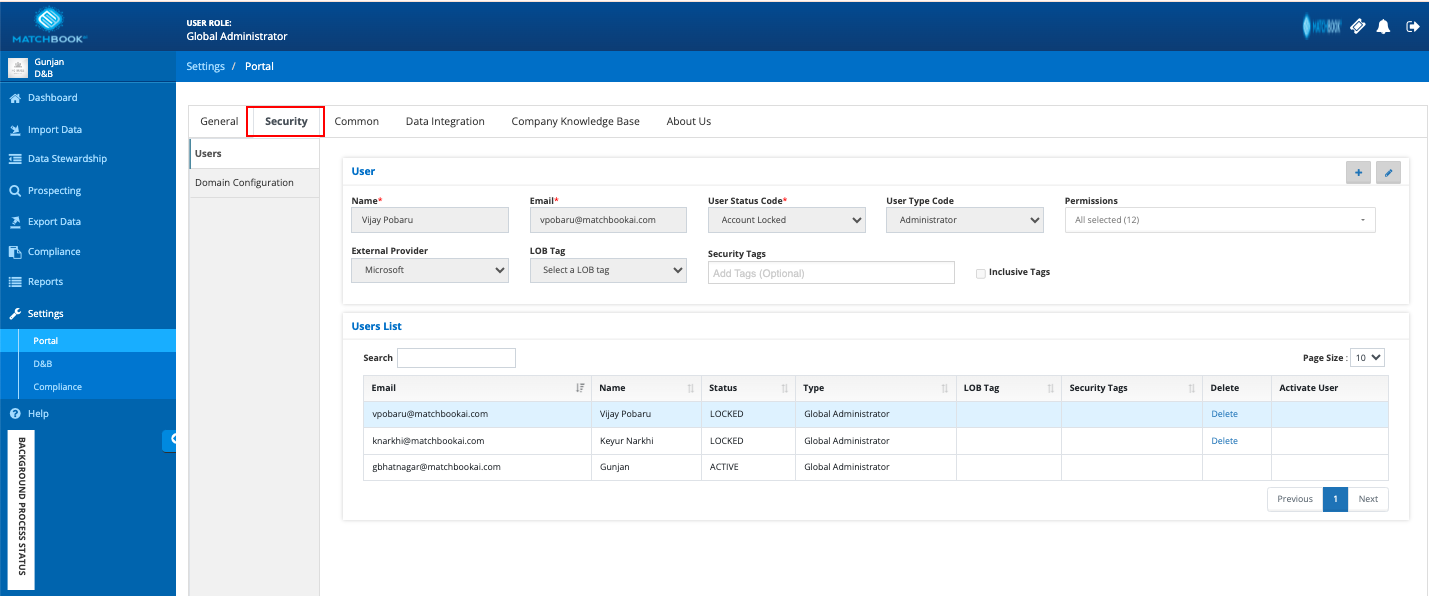
The Security section focuses primarily on user management within the portal. It encompasses two main tabs that allow administrators to add, edit, remove, or delete user accounts, ensuring secure and efficient control over user access and permissions. There are 2 main tabs under security
Settings-Security
Users
Add/Edit/Delete Users
Admin users can manage system users by adding, editing, or deleting them. To add or edit a user, click the ‘+’ or edit icons in the highlighted section below.
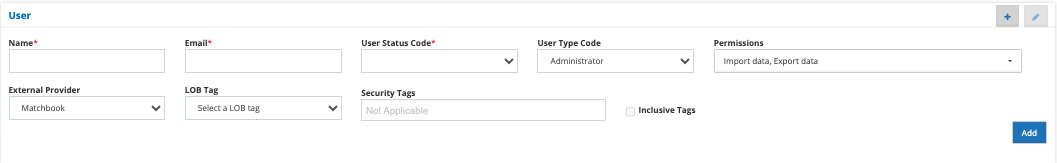
Add/Edit/Delete Users
Field |
Description |
|---|---|
Name |
Enter the name |
Enter a valid email id. |
|
User Status Code |
This feature enables the admin to manage user accounts. A list of account statuses has been provided below. |
User Type Code |
This functionality allows the admin to designate the role of each user within the system viz, Administrator or Data Steward. By assigning specific roles, the admin can control access levels and permissions, ensuring users have the appropriate authority and responsibilities in accordance with their designated role. |
Permissions |
This feature allows the admin to customize user permissions for specific functions within the system. The list of available permissions is provided below. |
External Provider |
External providers enable clients to select their preferred login method, including options such as Google, Matchbook, Microsoft, passwordless authentication, and Okta. Clients simply need to enable their chosen option to log in easily. Note: Matchbook serves as the standard login method, requiring two-factor authentication (2FA) for added security. |
LOB Tag |
These tags are utilized to categorize users effectively. A Line of Business (LOB) tag is assigned to group users together, enabling them to access and analyze data related to their specific tag. |
Security Tags |
Security tags are the same as LOB tags, assigned to group users together, enabling them to access and analyze data related to their specific tag. |
Inclusive Tags |
Select the checkbox if the user wants to assign the user to a specific group. |
Active: Activating an account grants the user access to the system.
Account Deleted: Deleting an account permanently removes it from the system.
Account Locked: Locking an account temporarily restricts user access.
Unauthorized: Deactivating an account revokes its authorization
Enable Investigations: Allows users to initiate investigations with D&B directly from the Matchbook Portal. Note: This requires separate entitlements with D&B.
Enable Reject Data: Grants users the ability to reject or purge multiple records from the system.
Enable Purge Data: Grants users the ability to reject or purge multiple records from the system.
Enable Search By DUNS: Provides users with the capability to search D&B data using DUNS numbers.
Enable Create Auto Accept Rules: Allows users to create and manage Auto Accept Rules.
Enable Preview Match Rules: Gives users the ability to view all match output data.
Enable Enrichment in UI: Allows users to access and view entitled enrichment data within the user interface.
After entering the necessary user details, the Matchbook Portal will generate an email to provide new users with their login information or update existing users accordingly.
In this section, you can view the list of users, search through the user database, and either delete or activate users as needed.
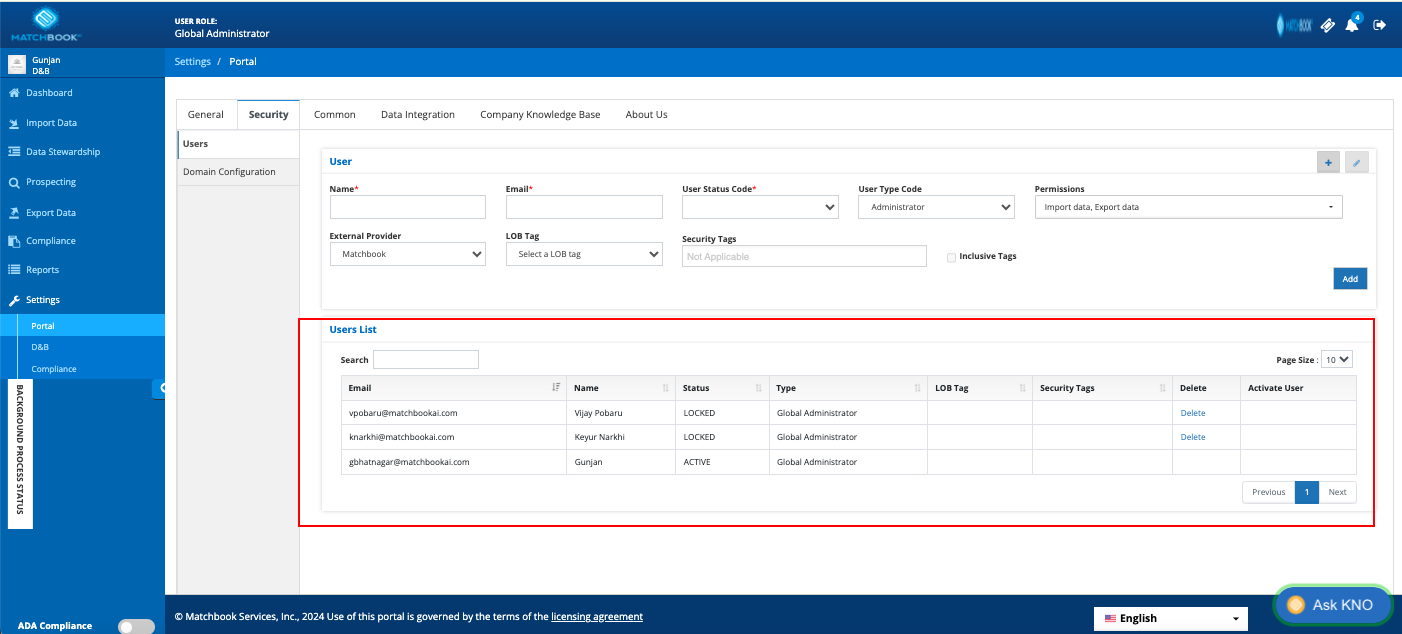
Users List
Note
When a user is deleted, they remain in the list for auditing purposes.
This feature allows you to configure email domains, ensuring that users must have one of the following three specified domains:
Beyondcode
Matchbookai
Matchbookservices.com
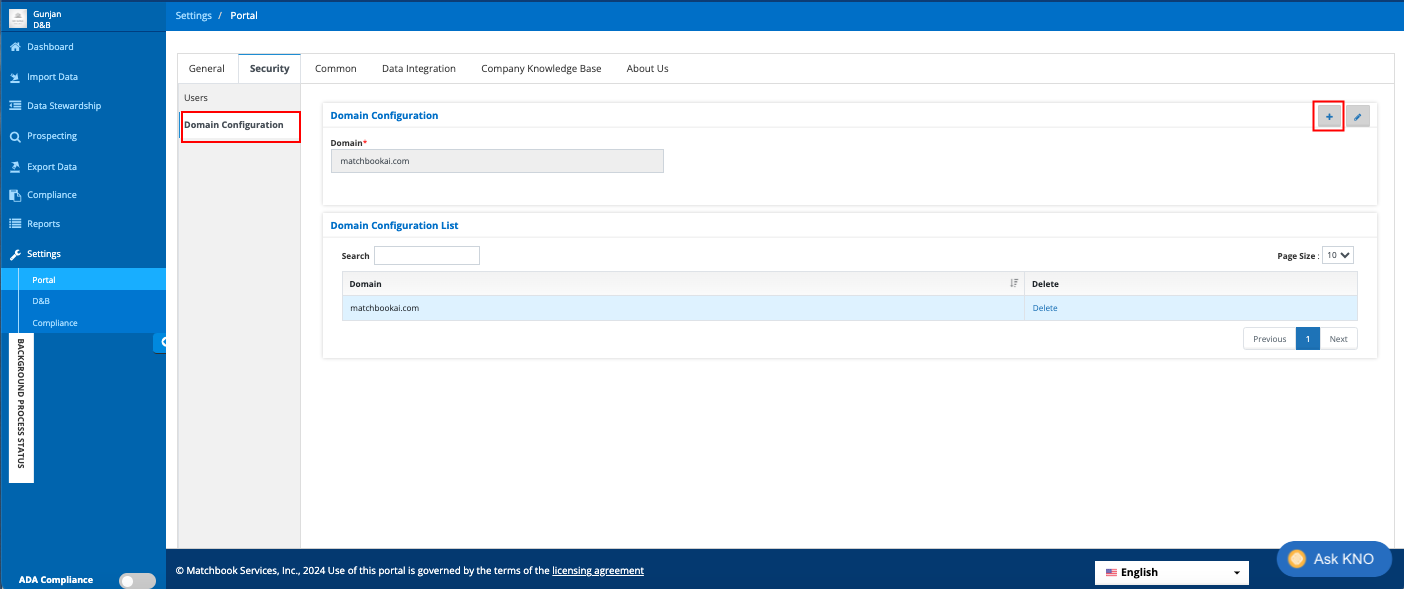
Domain Configuration
Note
If the user attempts to add a user with an email from a different domain, the process will not be successful.
To Add a new domain, click on the ‘+’ sign, enter the domain name in the designated box, and then click ‘Add.’
The Common section focuses primarily on groups, tags, destination and, export page settings within the portal. It encompasses six main tabs that allow administrators to access and permissions. There are 6 main tabs under Common:
Country Groups
Tags
User Comments
Export Page Settings
Export Destination
Encryption key
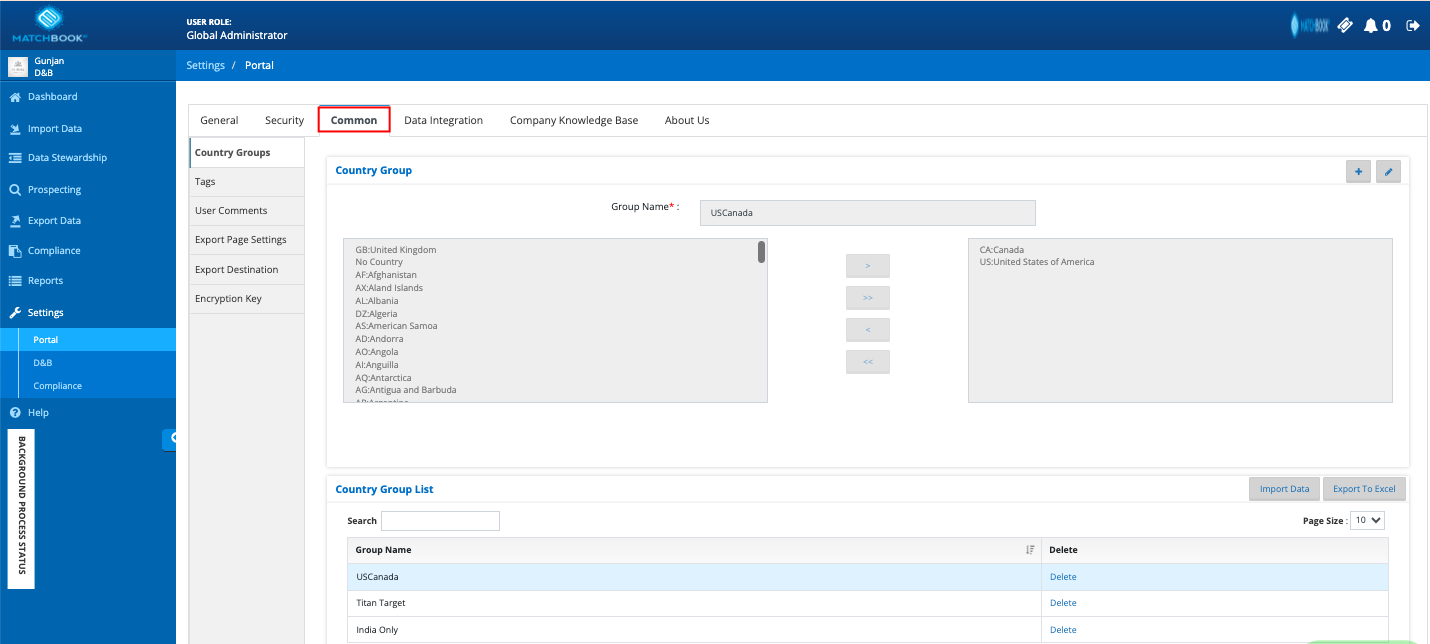
Settings-Common
Setting the country code is a critical step in ensuring that the matching process through the D&B API utilizes appropriate algorithms tailored for specific regions. By defining country groups, you enhance the accuracy and relevance of matches, leading to improved data quality and insights. This capability allows you to specify not just a single country but a group of countries, addressing a gap in D&B’s offerings for their clients.
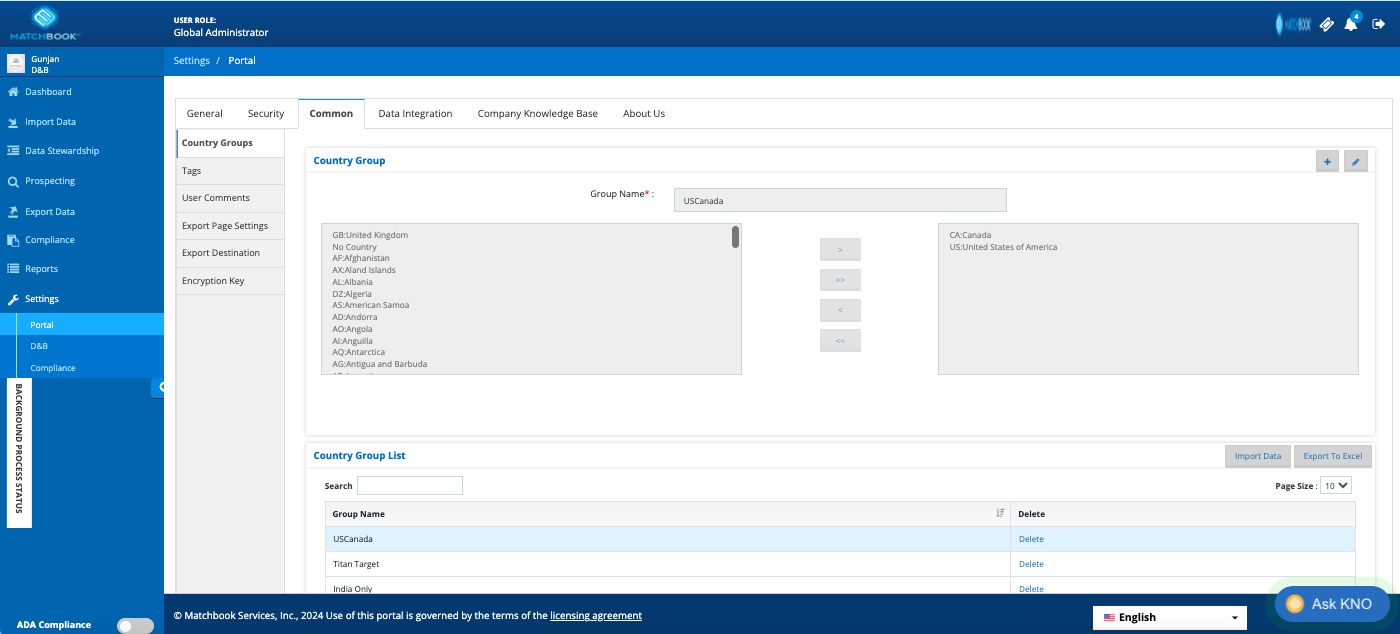
Settings-Common>>Country Group
For instance, consider a U.S.-based company with a record of suppliers located outside the U.S. If the internal data quality is low, it will likely match at a lower confidence level. This highlights the importance of country groups: by correctly configuring the country codes, companies can ensure that their matching processes account for geographical nuances, ultimately leading to better data interpretation and more reliable results.
Country groups allow you to create auto-acceptance rules tailored to specific regions. For example, you can create an auto-acceptance rule for records outside the US and apply different acceptance criteria. This helps in managing records efficiently and improving data quality.
Use Case: In the US, where data quality is generally higher, you can set an auto-acceptance rule to automatically accept records with confidence levels of 8, 9, or 10. Conversely, for regions like China, where data quality may be lower, you might set an auto-acceptance rule for confidence levels of 7, 8, and 9.
This flexibility allows the creation of multiple rules based on country groups. These groups can be region-specific or country-specific and can be customized for different data types, allowing you to tag them accordingly.
Country groups can also be utilized for data stewardship. For example, you can segregate your data stewards based on different countries: one team can handle all US clients, while another team manages all non-US clients.
Additionally, country groups can be used for enrichment purposes. For instance, in the US, a data governance team might require a registered number for suppliers, but for suppliers outside the US, D&B might not require any registered number. By using country groups, you can ensure that your data governance and enrichment processes are tailored to the specific requirements of each region.
The 3 Key records allow
Identity resolution based on country group for auto acceptance.
Data Stewardship filtering
Enrichment and Monitoring
Tags are a vital feature in the Matchbook Portal that facilitate effective data categorization and management. Individual files for API calls, match files, or SFTP servers, allowing for the application of different rules and criteria based on specific needs. By enabling the division of records and organizing them into distinct groups within an organization, tags enhance customized processing and ensure proper categorization prior to data import. Admins are responsible for creating and managing these tags, which can also be linked to Line of Business (LOB) tags for more structured organization. Tags are organized into categories such as Source, Security Group, and Monitoring Group, with each tag assigned specific values. This tagging system significantly improves organizational efficiency, leading to better data management and more reliable outcomes. Tags are very similar to country groups.
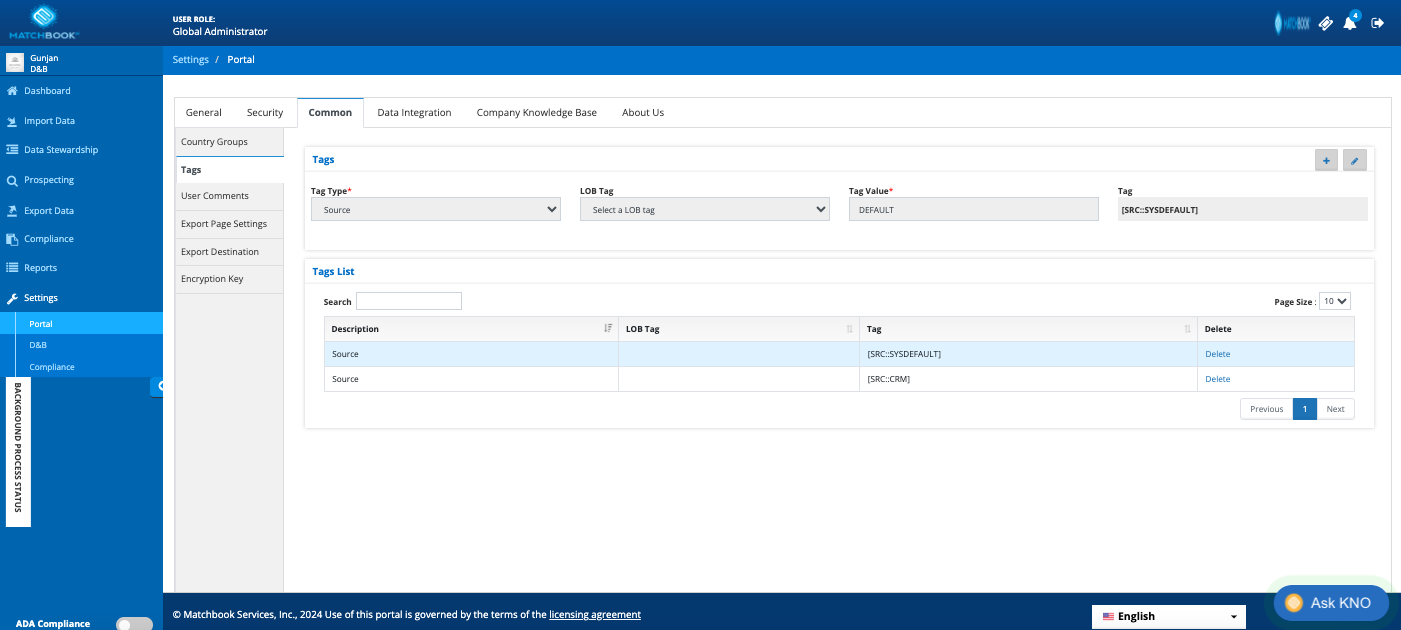
Settings-Tag
One can efficiently categorize the data by tagging all your U.S. records with a label like U.S. and all your non-U.S. records with a label like non-U.S. This method ensures consistent results and allows for streamlined data management.
Use Case: Imagine a company that operates in both the U.S. and international markets. The company has a comprehensive database of suppliers, some based in the U.S. and others in countries like Canada and China. By tagging all U.S. records with U.S. and all non-U.S. records with non-U.S., the company can easily apply specific rules to each group.
For instance, the company may have higher data quality standards for U.S. suppliers, so they could create an acceptance rule that automatically accepts records tagged as U.S. if they meet certain confidence criteria (e.g., confidence levels of 8, 9, or 10). Conversely, for records tagged as non-U.S., the company might implement a more stringent non-acceptance rule to ensure that only the highest-quality international suppliers are included in their operations.
This structured approach not only simplifies the processing of records but also enhances the accuracy of their supplier data. It allows the company to effectively manage risk and ensure compliance with varying regulatory standards across different regions, ultimately leading to more informed decision-making.
Users can also set enrichment tags for records, enabling automatic enrichment when a record matches the associated criteria. For instance, if a record is tagged with an enrichment label, the system will automatically enhance that record with relevant data tied to the tag, improving the overall quality and detail of the information.
Additionally, the monitoring feature allows users to create a tag that automatically adds a DUN’S number to a monitoring profile whenever a match is found. This proactive approach ensures that important data points are continuously tracked and managed.
Tags serve as powerful tools for mapping and filtering any attribute within your data, allowing users to easily match, steward, or query that data within the Matchbook console. This flexibility enables organizations to streamline data management processes and maintain high-quality records.
Moreover, tags can be utilized to label data for better organization and identification, further enhancing the effectiveness of data management within the system. By categorizing records through tagging, clients can optimize their data handling processes and ensure that their operations align with specific business requirements.
Tags in Matchbook AI are a method of creating different workflows. A user can have different considerations such as different types of data coming into the system or different teams working on their data. Based on business requirements they might have different needs for retrieving and importing data. Tags serve to establish various workflows with distinct requirements and sets of rules for the retrieval and handling of data. Once a tag is set up, it can serve multiple purposes. The most used type of Tag is the source tag. The Source Tag helps manage data from various origins, e.g., a tag-marketing, finance, or hr etc., can be assigned to data originating from different organizational departments. To add tags, perform the following steps.
Click on the “+” icon at the top right to add a new tag.
Select the tag type from the list of options provided in the dropdown menu, for e.g. To tag the data based on the source of origin select the Source tag.
Select the LOB (Line of Business) tag from the list of options provided in the dropdown menu.
Enter the Tag Value. For example, Marketing. The tag will be generated based on the value provided.
Click Add. The newly created tag will be added to the system.
Note
If the security tag is applied to any Data or group of Data, it will be hidden from anyone who is not entitled to that tag. Only platform users that have been assigned the security tag have permission to view the data.
Assigning a Line of Business (LOB) tag determines what an individual can view on the platform. This is especially important for users who should not have access to internal data. Importing data with a security tag aids in maintaining the confidentiality of the data. Any user wanting access to the data must have security clearance assigned to their user profile. If a user’s role lacks the required security tag, they won’t be able to access the portal.
DnB
The DnB tab features five sections. These have been described below.
General
License
Identity Resolution
Data Enrichment
Monitoring Direct+
General Settings
The General tab includes two primary settings
Activates the cleansing process to refine and standardize data during import.
Activates the enrichment process, where additional data is appended to existing records to enhance their quality and completeness.
Use Case: If a client wishes to process records through the platform solely for an initial cleanse match without performing data enrichment, they can pause the data enrichment feature. This can be done by navigating to the General settings and switching the toggle button to disable data enrichment.
These features can be paused by returning to the dashboard, selecting the appropriate toggle button, and pausing the corresponding feature.
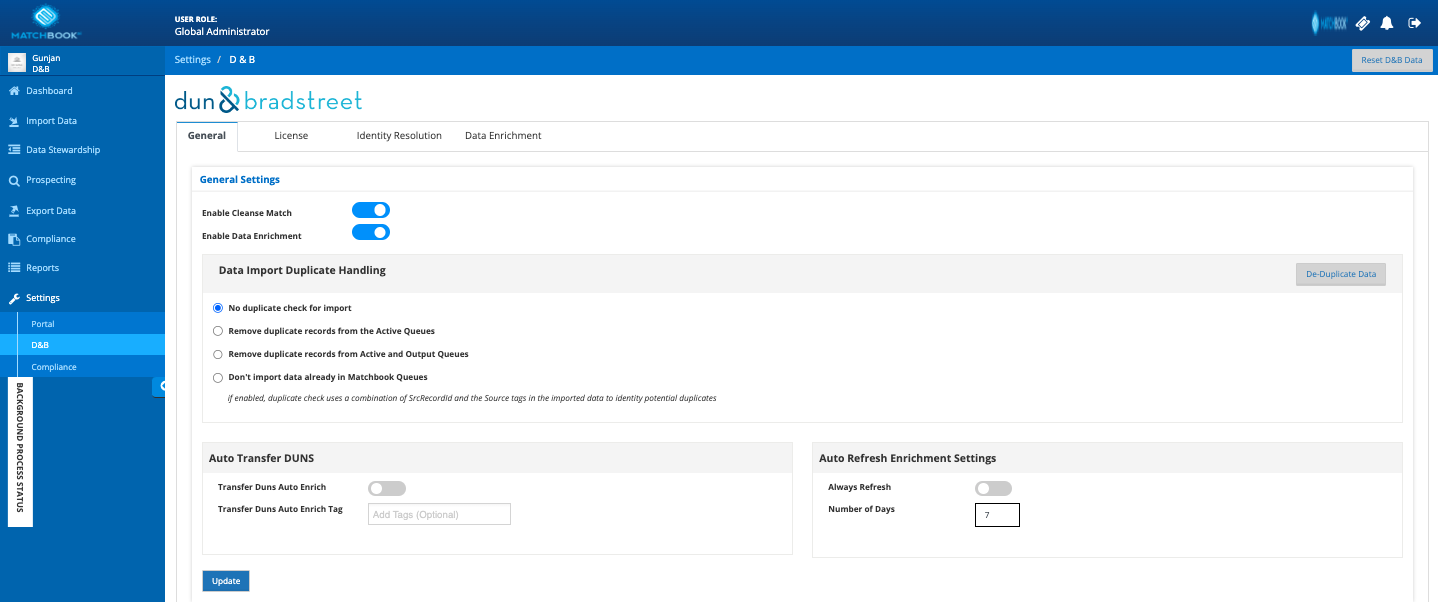
Settings
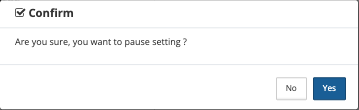
Settings
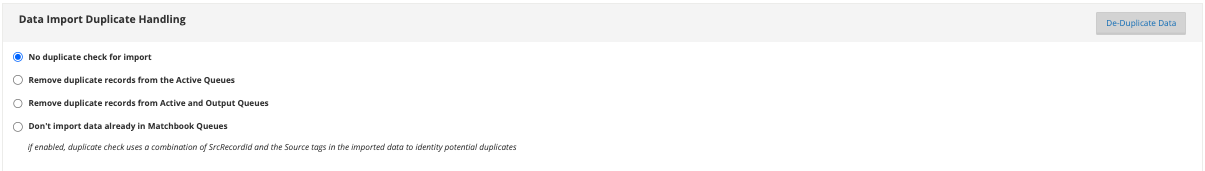
Controls how duplicates are managed during the data import process using tags and Source Record IDs.
Use Case: When importing records for companies named Microsoft, the system will focus on the Source Record Id rather than attributes like company information. For example, if two records both refer to Microsoft but have different source IDs, the system will check these Source Record Id values to determine if they are duplicates. This approach ensures that records are differentiated based on their unique identifiers rather than their names or other attributes.
Settings
There are 4 different methods in which matchbook can process duplicate records. The settings include:
No duplicate check for import: Disables the check for duplicate records during import, allowing all records to be imported regardless of duplicates. This process can also be performed manually by clicking on the De-duplicate Data tab.
Remove Duplicate Records from the Active Queues: Deletes duplicate records from the queues currently being processed, ensuring that only unique records are handled. This applies to all records in active queues, such as low confidence, no match, and match output queues.
Use Case: if a record with source record ID 01 is placed in the low confidence queue and a new record with the same source record ID 01 is later sent, the new record will be processed while the older record in the low confidence queue will be removed. The most recent import is retained, and the older record is deleted.
Remove Duplicate Records from Active and Output Queues: Removes duplicates from both the active processing queues and the final output queues to ensure uniqueness across all stages.
Don’t Import Data Already in Matchbook Queues: Prevents importing records that already exist in Matchbook queues.
Use Case: if a record with source record ID 01 is placed in the low confidence queue and a new record with the same source record ID 01 is later sent, the most recent import is deleted, and the older record is retained.
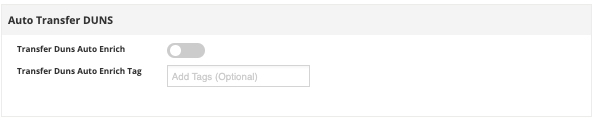
Automatically transfers DUNS numbers to other systems or processes as part of the data integration workflow.
Settings-Auto Transfer DUNS
Transfer DUNS Auto Enrich: Enables automatic enrichment of DUNS records during the transfer process, ensuring that DUNS numbers are enriched with additional data. When a dun’s number is transferred
Transfer DUNS Auto Enrich Tag: Applies a specific tag to DUNS records that are auto enriched during the transfer process, helping to categorize and track enriched records.
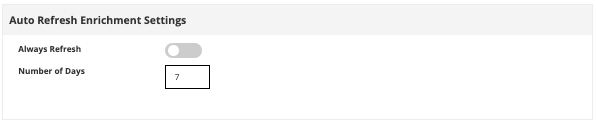
Controls the automatic refreshing of enrichment settings.
Auto Refresh Enrichment Settings
Always Refresh: Ensures that enrichment settings are continually updated to reflect the most current data and rules.
Number of Days: Specifies the frequency of automatic refreshes, with the default set to every 7 days. This ensures that enrichment data remains current and accurate.
Click on Update to complete the action.
License
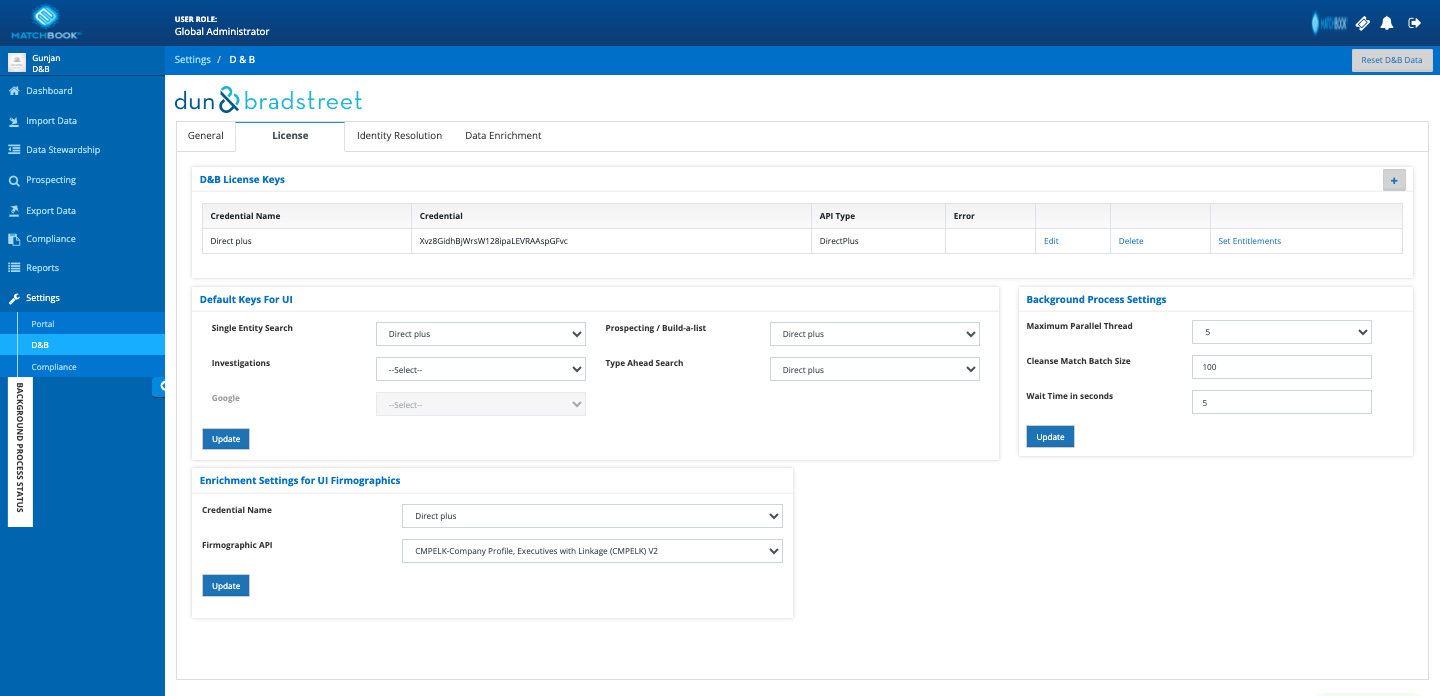
D&B License Keys provide the necessary credentials and API types for accessing various data services. These keys are essential for performing functions such as entity searches, prospecting, and investigations within the platform. Proper management of these licenses ensures seamless integration and functionality across different D&B services.
License
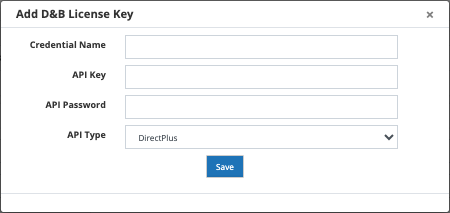
License-Add DnB License Key
Credential Name: Enter a descriptive name for the license.
API Key: Input the unique API key provided for authentication.
API Password: Enter the associated password for the API key.
API Type: Select the type of API service from the available options in the drop-down menu.
Complete the process by saving the new license key details.
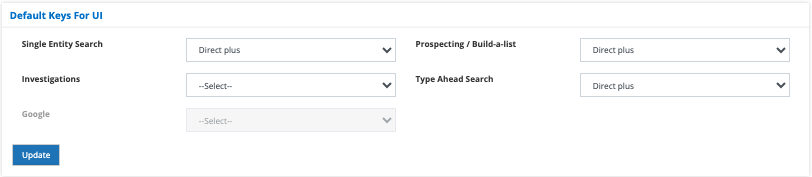
Default Key For UI
Single Entity Search: Utilizes the Direct Plus API for detailed searches of individual entities. Select from the drop-down menu.
Prospecting / Build-a-list: Employs the Direct Plus API for generating and managing lists of prospects. Select from the drop-down menu.
Investigations: Requires selection of an appropriate API for conducting investigations. Select from the drop-down menu.
Type Ahead Search: Configured with Direct Plus or Google APIs for predictive search functionality. Select from the drop-down menu.
After selecting the desired API type for each function click Update.
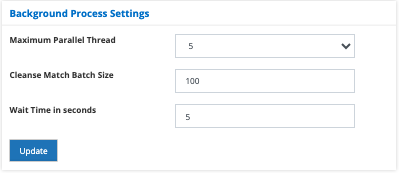
Background Process Settings
Maximum Parallel Thread: Limits the number of concurrent threads to 5, optimizing performance and resource use. Select the option from the drop-down menu.
Cleanse Match Batch Size: Sets the batch size to 100 records for each cleanse match process, balancing speed and accuracy.
Wait Time in Seconds: Configures a delay between processes, ensuring smooth operation and system stability.
Click Update to save the changes.
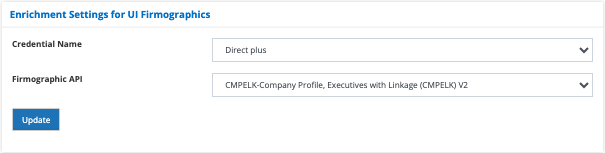
Enrichment Settings for UI Firmographics
Credential Name: Identifies the credential used for accessing the enrichment service. Select from the options available in the drop-down menu.
Firmographic API: Specifies the “Direct plus” API used for firmographic data enrichment, ensuring that company profiles and executive information are accurately retrieved and displayed. Select from the options available in the drop-down menu.
The Reset D&B Data button, located on the top right-hand side, is exclusively available to the development department. When the Reset D&B Data button is clicked, a confirmation box appears. To confirm the reset, type YES in the text box and then click on Reset.

Reset D&B Data
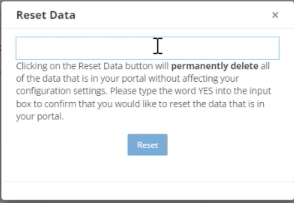
Reset D&B Data-Config
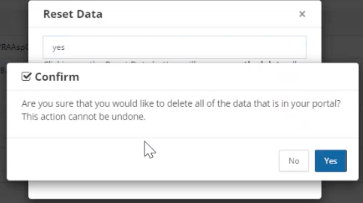
Reset D&B Data-Confirm
This action will reset all the data in the queue.
Identity Resolution
Identity Resolution in Matchbook AI’s D&B integration ensures that input records are accurately matched to the correct entities in Dun & Bradstreet’s database. Administrators can configure rules, thresholds, and scoring to control how matches are identified, validated, and approved- reducing false positives, minimizing manual review, and improving data quality across the platform.
Minimum Match criteria
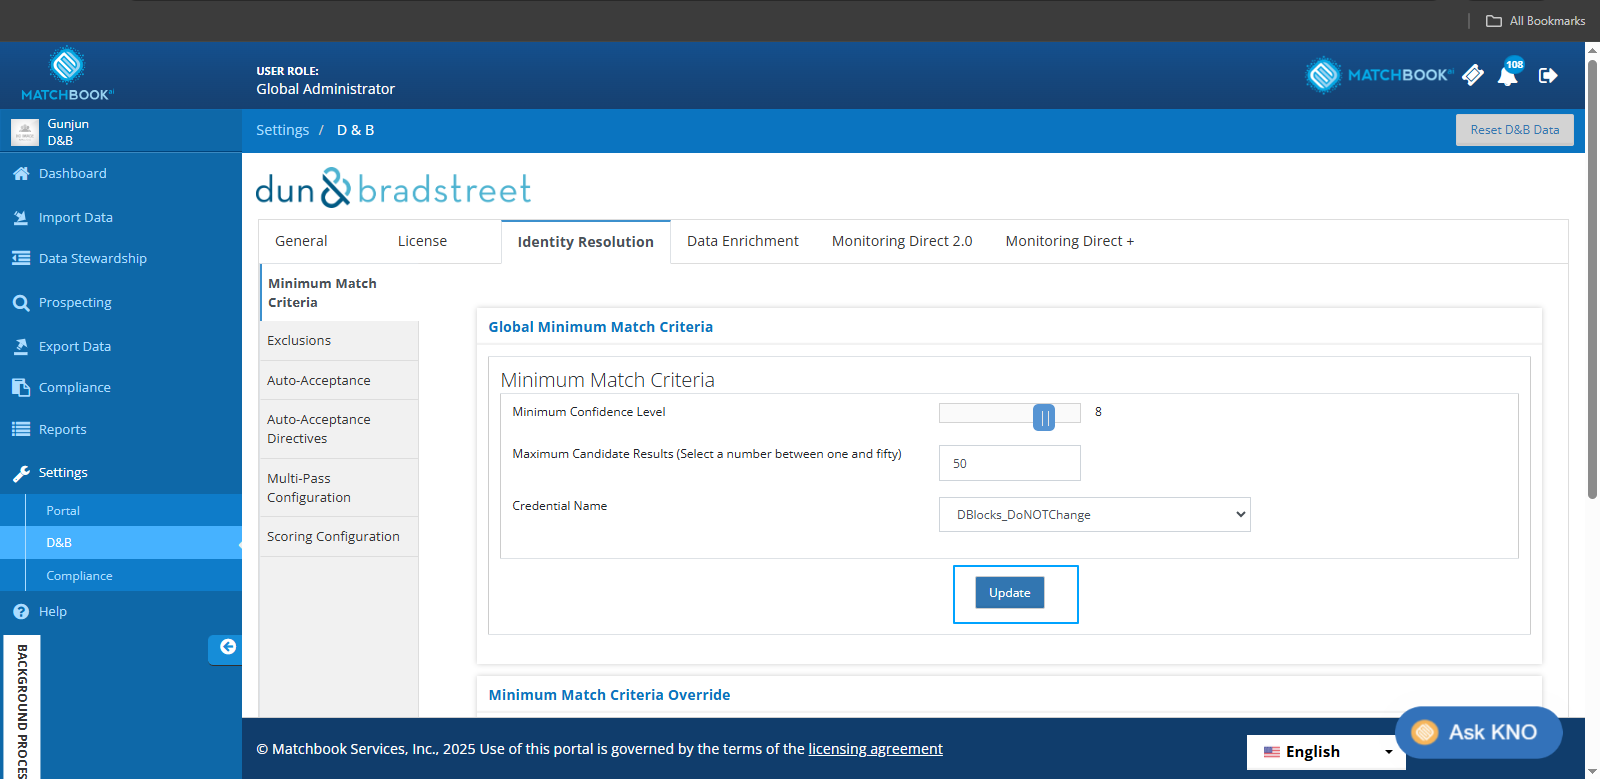
The Minimum Match Criteria section in the D&B settings allows administrators to define and manage the baseline thresholds for determining whether a potential match between an input record and a D&B candidate should be considered valid.
You can access this section via:
Settings → D&B → Identity Resolution → Minimum Match Criteria
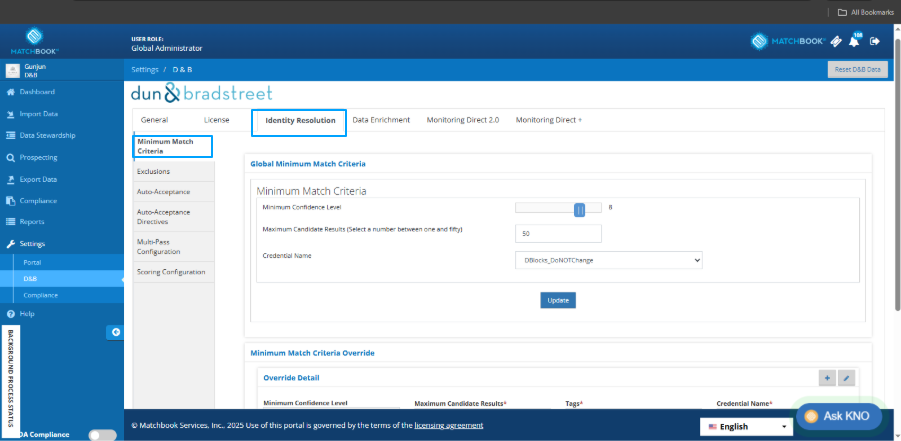
It is divided into 2 sections: Global Minimum Match Criteria and Minimum Match Criteria Override. Let’s go through them one by one.
Global Minimum Match Criteria
This section sets the baseline thresholds applied universally across all matching operations.
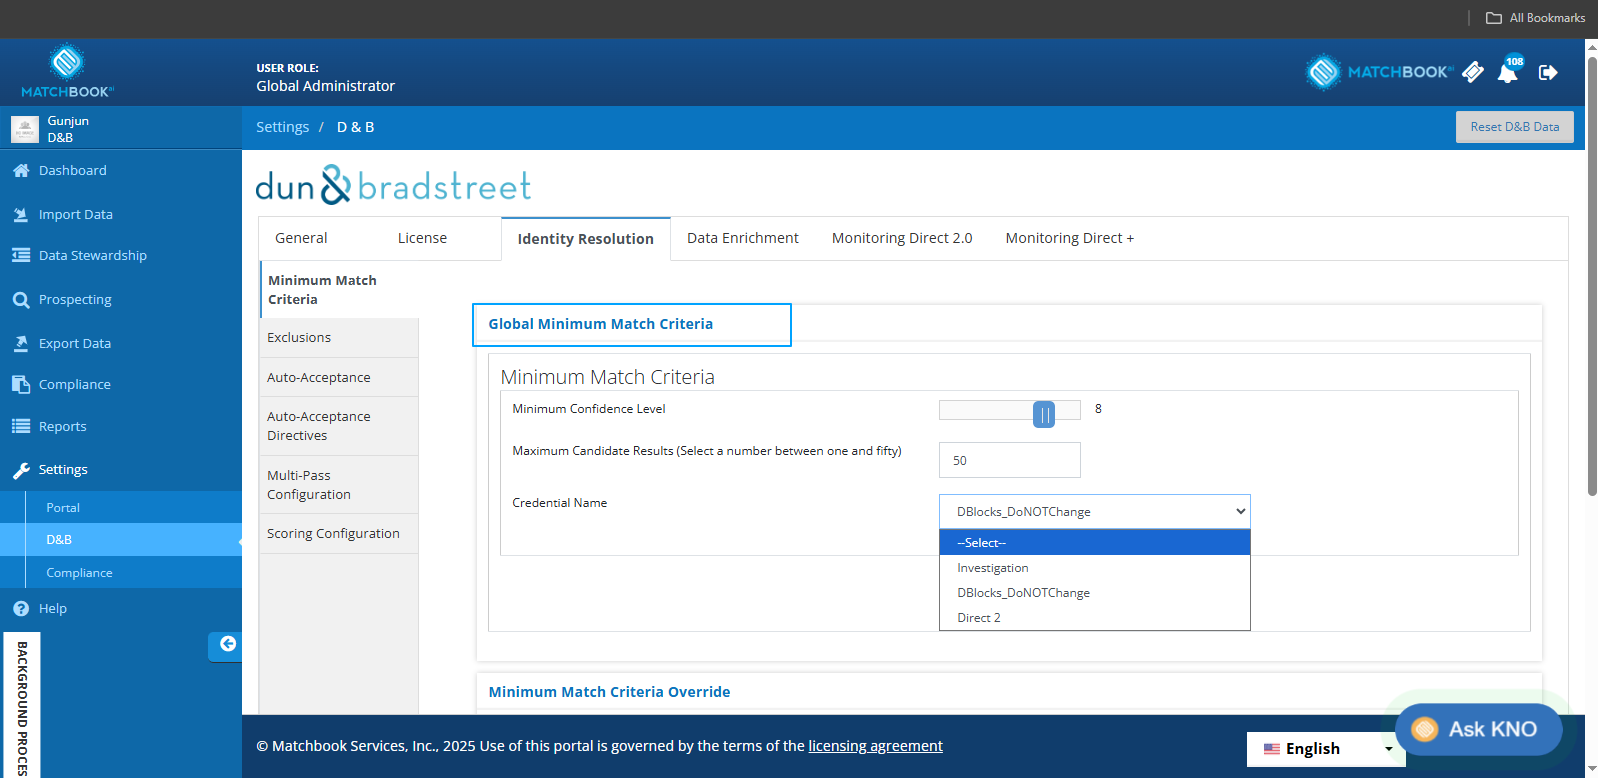
It includes:
Column Name |
Description |
|---|---|
Minimum Confidence Level |
Defines the lowest acceptable confidence score for a candidate to be considered. Here the default value is 8. |
Maximum Candidate Results |
Sets the upper limit on how many match candidates to return per input (here, you must select a number between 1 and 50). |
Credential Name |
Specifies the credential under which these global settings apply (For example, Investigation, DBlocks_DoNotChange, Direct 2). |
These parameters act as a global gatekeeper, ensuring that only sufficiently strong matches proceed for further evaluation.
Once the required values are entered, click Update.
Minimum Match Criteria Override
Overrides allow for fine-tuned exceptions to the global rules. This section lets administrators configure alternate thresholds based on contextual tags or data segments.
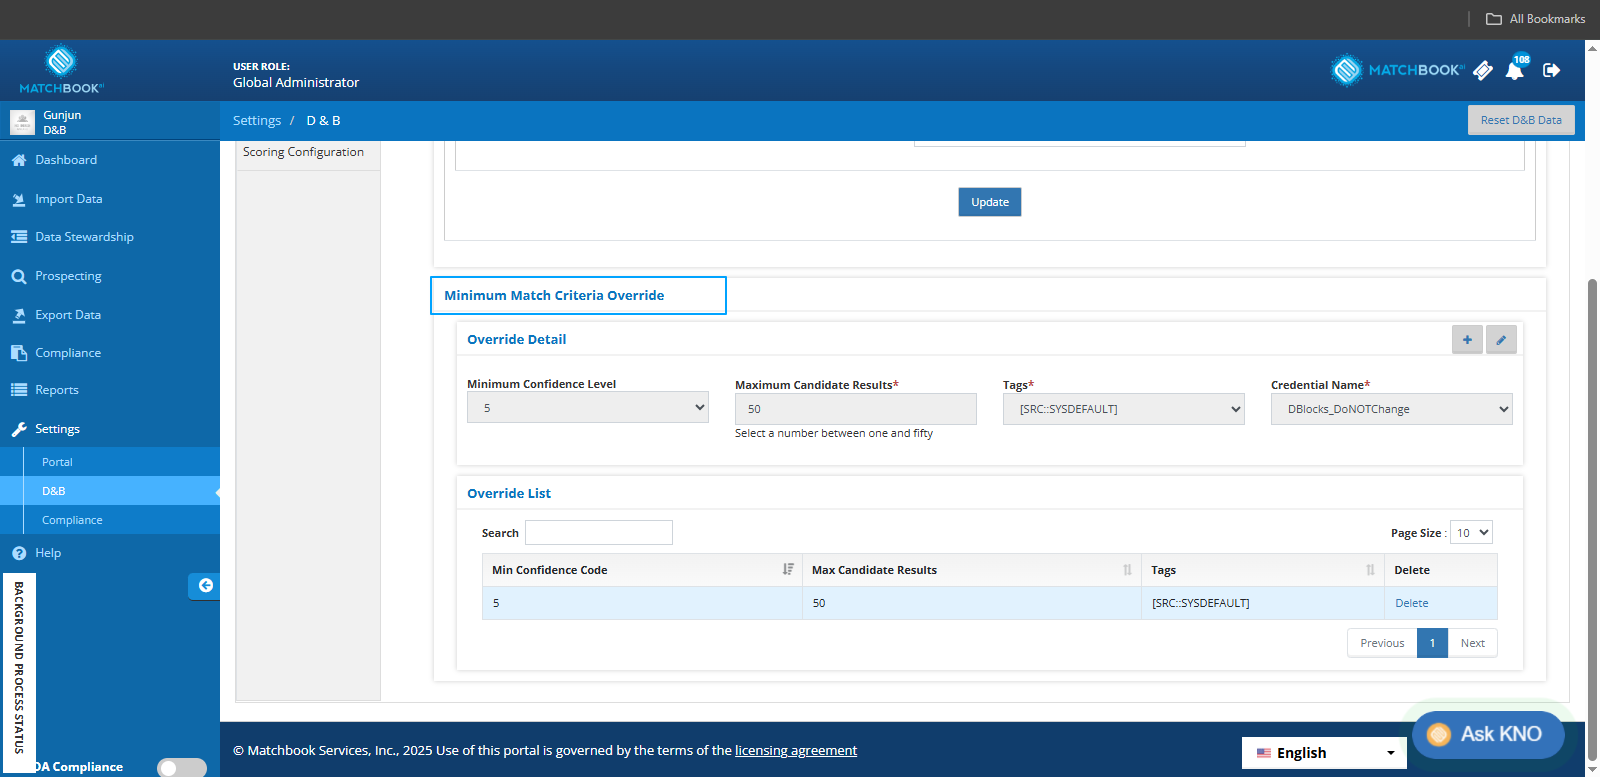
The section is divided into two key sub-sections:
Override Detail
This sub-section allows administrators to define a new override rule before saving it into the list of active overrides.
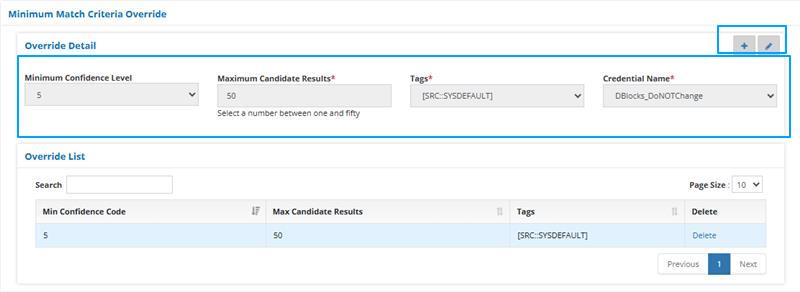
There are 2 buttons on the right.
Add (➕) button: It saves a new override rule based on the values currently selected in the Override Detail fields.
Once you have filled in the required fields such as Minimum Confidence Level, Maximum Candidate Results, Tags, and Credential Name, clicking this button adds the rule to the Override List below.
It validates inputs before saving to ensure completeness and prevent duplicate rules.
Note
When you attempt to create a new override using the Add (➕) button, and if the system detects that an override rule already exists for the same Tag and Credential Name combination, then this message is displayed: “There is already an override rule set for this tag. Please update the existing record”.
Edit (✏️) button: It allows modification of an existing override rule that appears in the Override List.
When you select an entry in the Override List, clicking the Edit button populates the Override Detail fields with the selected rule’s values.
This enables easy updating after making changes, click the Add button again to overwrite the original rule with the updated settings.
It contains the following fields:
Fields |
Description |
|---|---|
Minimum Confidence Level |
Sets the lowest acceptable match confidence score for this override. (For example, from the drop-down menu, select a value of 5 which means, only matches with a confidence score of 5 or above are accepted under this rule). |
Maximum Candidate Results |
Determines how many candidate records should be retrieved during the match process (For example, a value of 50 restricts the result set to a maximum of 50 candidate matches). |
Tags |
Acts as a targeting mechanism to apply overrides only when certain business or data context tags are present (For example, from the drop-down menu, select SRC::SYSDEFAULT, which means this override applies when this system-level source tag is detected in the data). |
Credential Name |
Specifies the data credential or environment context under which the override applies (For example, from the drop-down menu, select DBlocks_DoNotChange, which indicates that the rule is applied within this specific credential scope). |
Once all fields are populated, the override can be added to the list for enforcement.
Override List
This sub-section displays all previously configured and saved override rules. It enables visibility, search, and management (e.g., deletion) of active override configurations.
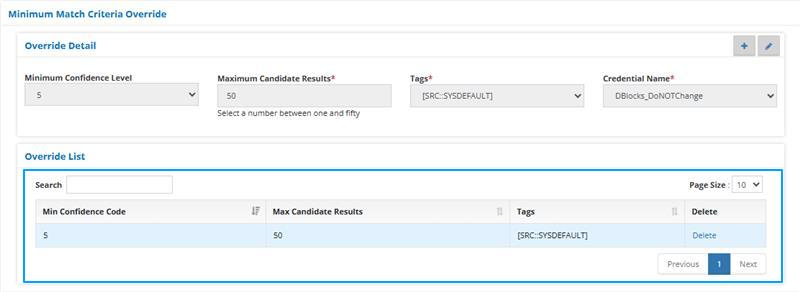
The Search box allows users to quickly filter and locate specific override rules among potentially many entries.
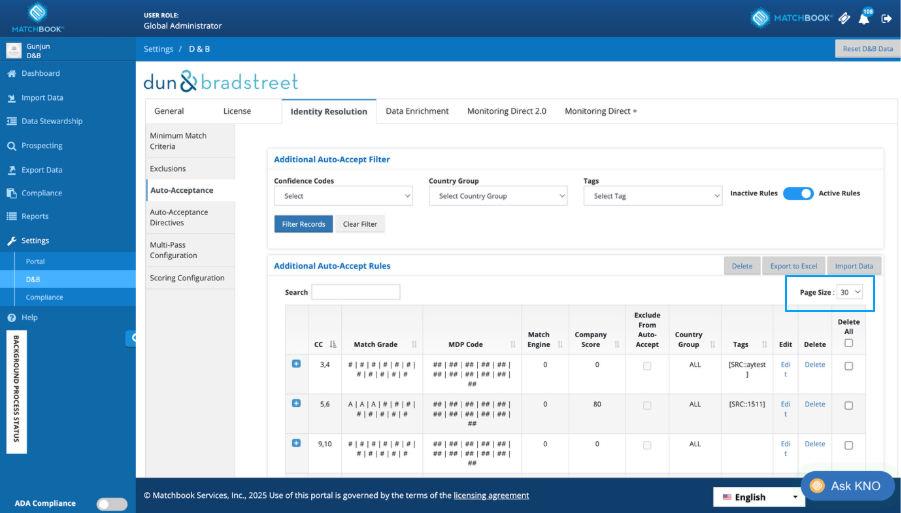
Use the pagination controls on the right, next to Page Size. From the drop-down menu, select the desired number of records to display per page.
The key columns are:
Fields |
Description |
|---|---|
Min Confidence Code |
Displays the minimum confidence score defined in each override rule. |
Max Candidate Results |
Shows the cap on candidate records returned during match evaluation. |
Tags |
Indicates the tag conditions under which the override is active. |
Delete |
Provides the option to remove an override from the active list when it’s no longer relevant or needs to be updated. |
These criteria directly influence the quality and breadth of match candidates and serve as a foundational filter before any advanced logic such as auto-acceptance, exclusions, directives, or multi-pass verification is applied. Fine-tuning these settings ensures the platform returns a balance of comprehensive yet precise match candidates, supporting downstream decisions including auto-acceptance and manual review.
Exclusions
The Exclusions section provides configurable filters that eliminate specific types of candidate records from the identity resolution process. These rules help refine match results by excluding undesirable, invalid, or low-quality entities before final candidate selection and scoring occurs. Each exclusion can be enabled globally or applied selectively using tags, making this system highly flexible for complex, multi-candidate scenarios.
Access this via:
Settings → D&B → Identity Resolution → Exclusions
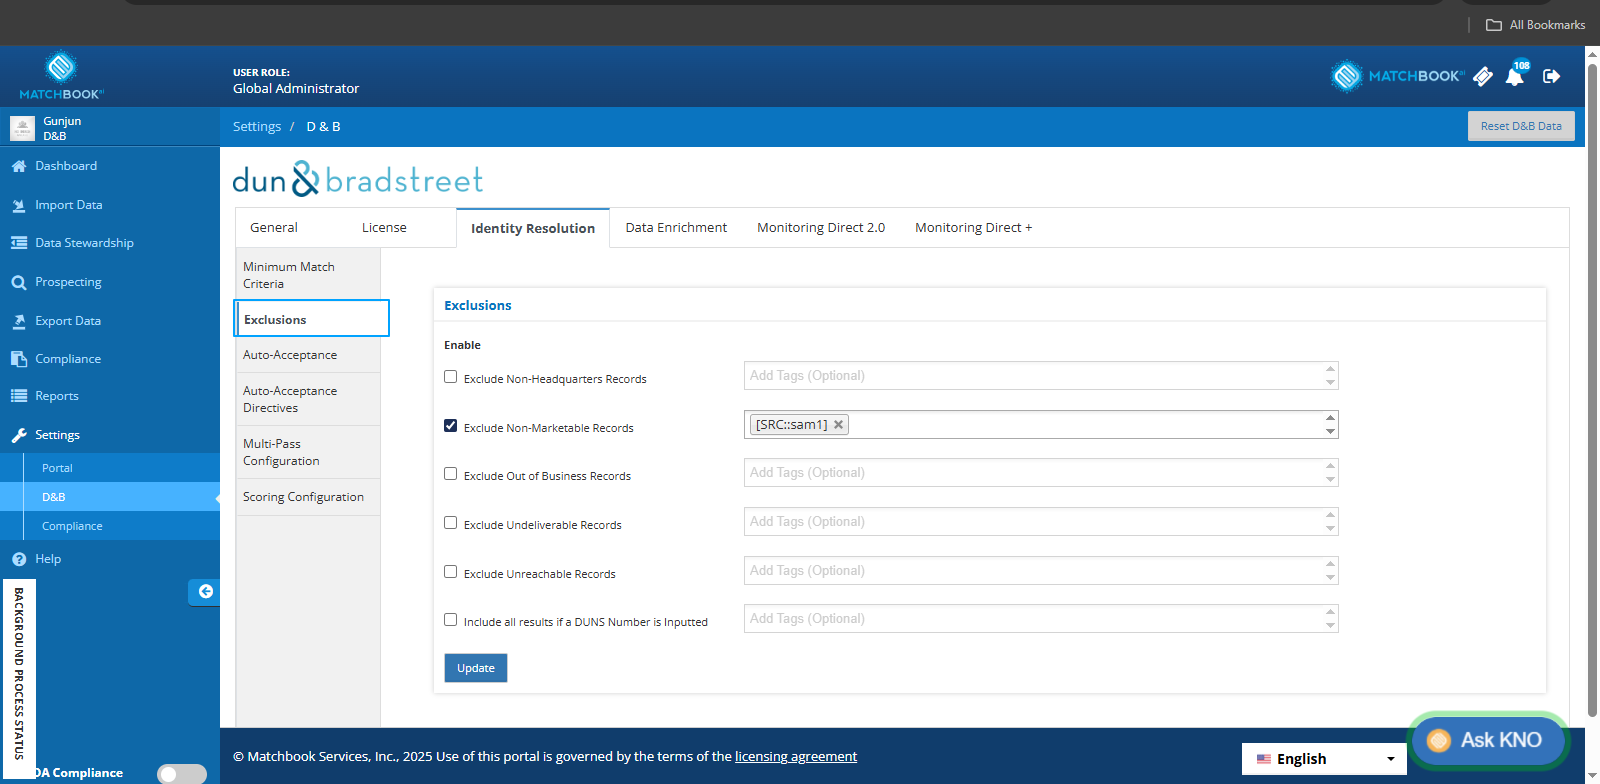
Exclusion Options
From the above screen, you can see there are 6 exclusion options available.
Exclusion Options |
Description |
|---|---|
Exclude Non-Headquarters Records |
Removes branch or subsidiary records when a headquarters record is present. Note: From the drop-down menu, choose a tag selector with options like:[ENR::DATA_NK], [SEC::1503], [SEC::NK], [SEC::oct8ay], [SRC::sam]. These tags enable contextual application of exclusion rules based on source systems, enrichment layers, or business scenarios. |
Exclude Non-Marketable Records |
Filters out records deemed not suitable for marketing purposes (From the drop-down menu, choose a tag selector). |
Exclude Out of Business Records |
Excludes entities flagged as no longer operating (From the drop-down menu, choose a tag selector). |
Exclude Undeliverable Records |
Eliminates candidates with delivery issues. For example, invalid mailing addresses (From the drop-down menu, choose a tag selector). |
Exclude Unreachable Records |
Removes records with disconnected phone numbers, missing emails, or other inaccessibility flags (From the drop-down menu, choose a tag selector). |
Include All Results if a DUNS Number is Inputted |
Overrides other exclusions and includes all match candidates when a known D-U-N-S® Number is provided (From the drop-down menu, choose a tag selector). |
Note
Each exclusion has a tag selector with options like: [ENR::DATA_NK], [SEC::1503], [SEC::NK], [SEC::oct8ay], [SRC::sam]. These tags enable contextual application of exclusion rules based on source systems, enrichment layers, or business scenarios.
Once the required checkboxes are selected with the tag selector, click the Update button to save and apply the exclusion rules. This action ensures that the specified filters are enforced during identity resolution, scoped either globally or under the defined tags, depending on your configuration.
Auto Acceptance
Matchbook’s Auto Acceptance feature under D&B Settings-> Identity Resolution enables automated handling of low-confidence match candidates by applying configurable business rules. This significantly reduces manual review effort while maintaining consistency and precision in entity resolution.
Using rule-based criteria, including confidence codes, match grades, company scores, and country groups, this feature determines which records can be auto-accepted and routed directly to downstream workflows. Auto Acceptance supports:
Scalable resolution of large record volumes with minimal intervention
Customizable acceptance rules by tag, geography, or data provider
Improved match quality through embedded scoring logic and exclusions
Operational efficiency with reduced need for steward review
You can access Auto Acceptance configuration via:
Settings-> D&B-> Identity Resolution-> Auto-Acceptance
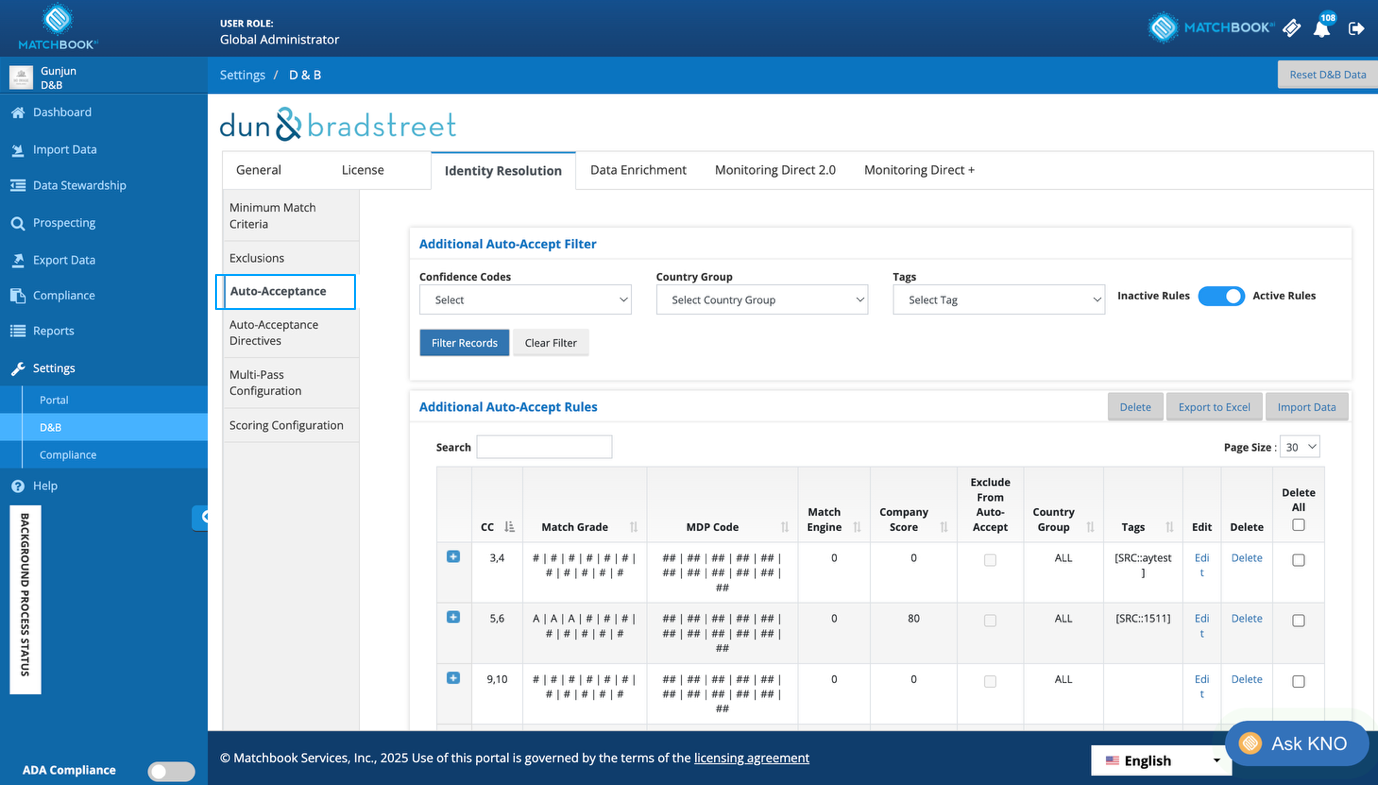
The screen includes top-level filters (e.g., Confidence Codes, Country Group, Tags) to manage and view rule configurations. Rules can be executed, filtered, edited, imported, exported, or deleted directly within the interface.
Note
For more information on Identity Resolution with DnB data, see this resource: https://directplus.documentation.dnb.com/html/guides/Identify/IdentityResolution.html . User login is required to access DnB documentation.
Navigating the Auto-Acceptance Interface
The Auto-Acceptance interface allows users to define and manage rules that automatically approve candidate matches based on business criteria.
It’s accessible via:
Settings → D&B → Identity Resolution → Auto-Acceptance
The screen is divided into two main sections: top-level filters and a rule configuration table.
Additional Auto-Accept Filter
Use this section to narrow down which rules are displayed. These filters have been described below.
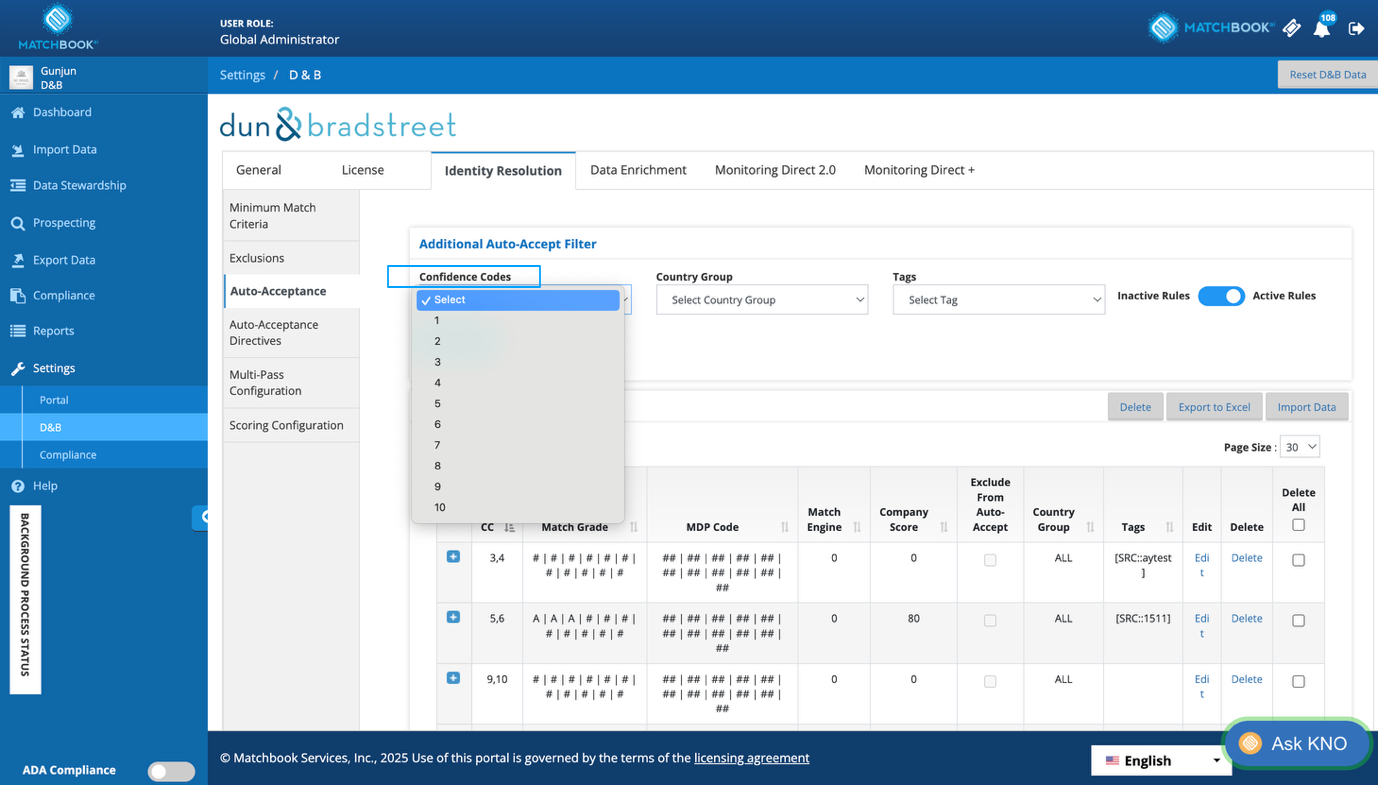
Confidence Codes: D&B match confidence thresholds (1-10; 1 being the lowest and 10 the highest match confidence).
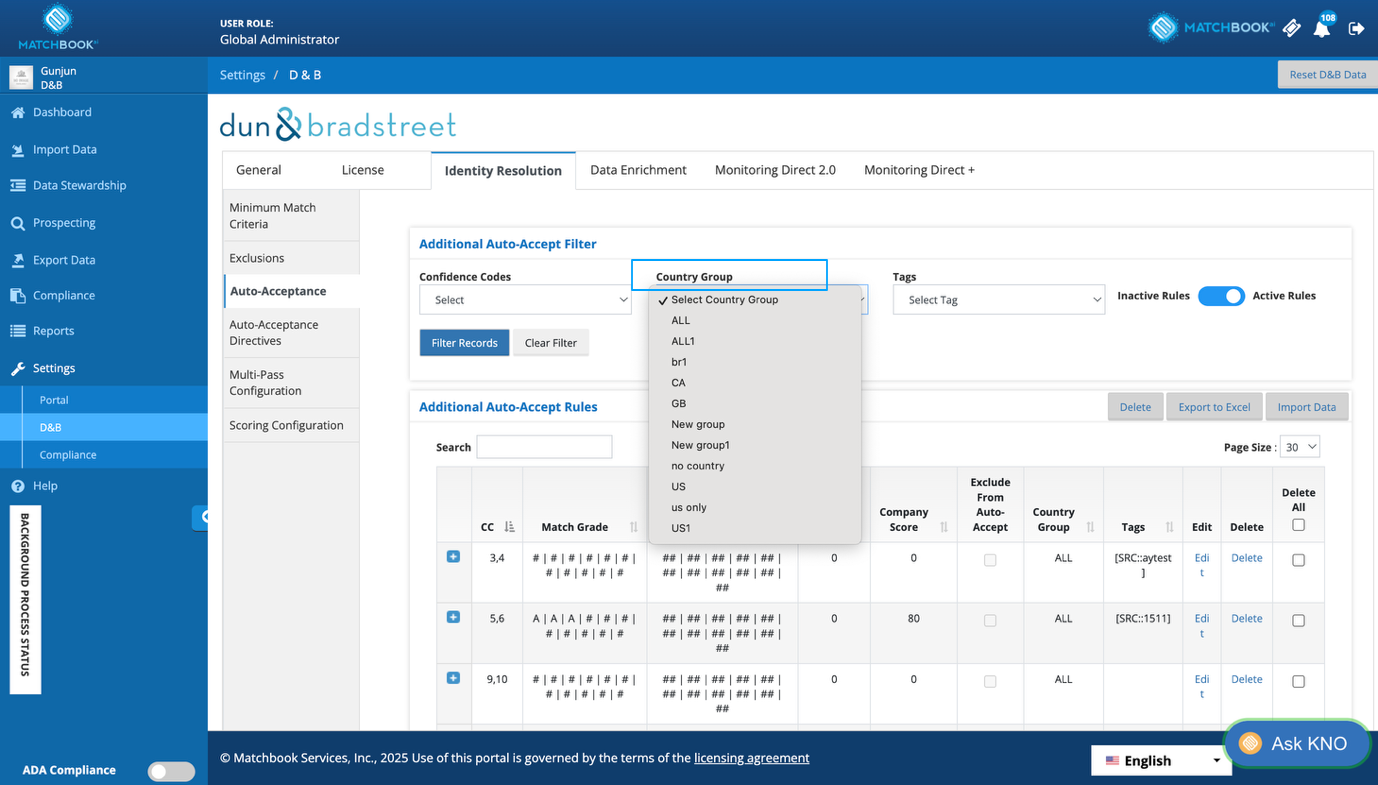
Country Group: Applies auto-accept rules based on country-specific logic. Defined in Settings->Portal.
Tags: Business-defined labels used to scope rules to specific data contexts. Defined in Settings->Portal.
Rule Status Toggle: View Active or Inactive rules.
Filter Records: Apply the selected filters
Clear Filter: Reset all filters
Additional Auto-Accept Rules
This table lists existing rules and supports editing, deleting, or creating new ones.
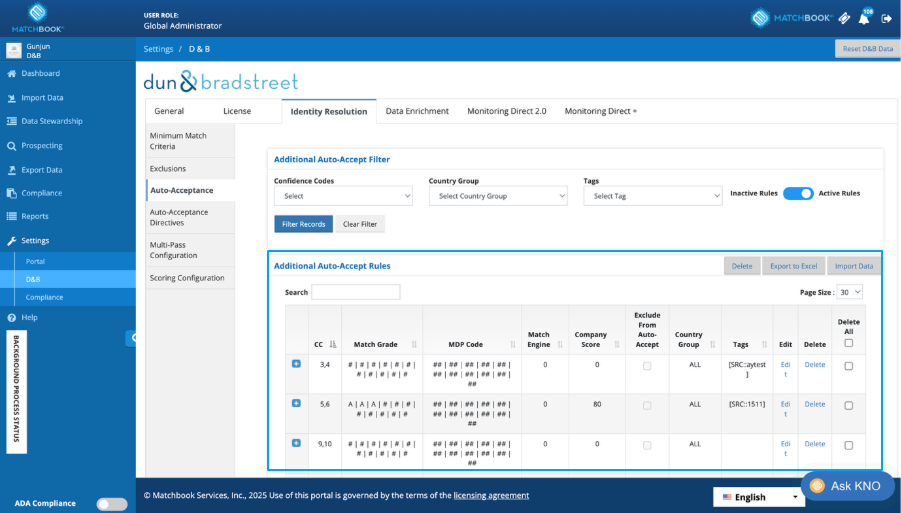
The table below gives the description of each column
Columns |
Description |
|---|---|
CC |
Confidence Code(s) the rule applies to |
Match Grade |
Accepted match grade patterns |
MDP Code |
Required Match Data Profile codes |
Match Engine |
Optional- used for engine-specific logic |
Company Score |
Minimum score for a candidate to be considered |
Exclude From Auto-Accept |
Marks rules as exceptions, not used during evaluation |
Country Group |
Limits rule scope to records from defined countries |
Tags |
Restricts rules to records with matching tags |
Edit/Delete |
Modify or remove the rule |
Delete All (checkbox) |
Bulk delete selection |
Additional Actions
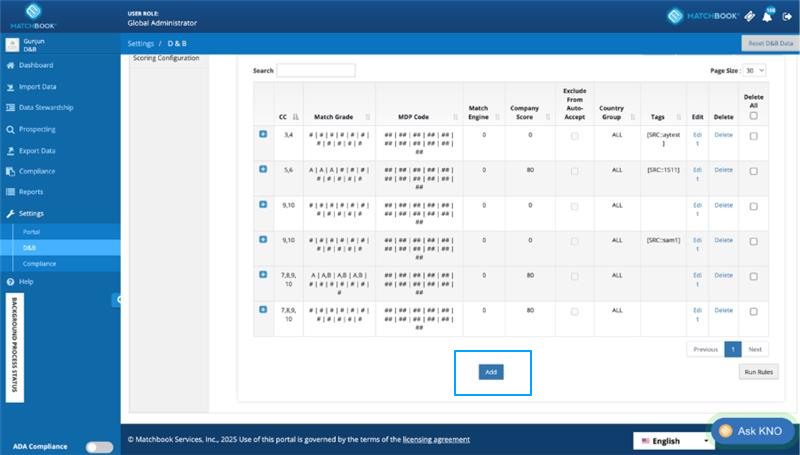
Add: Create a new rule
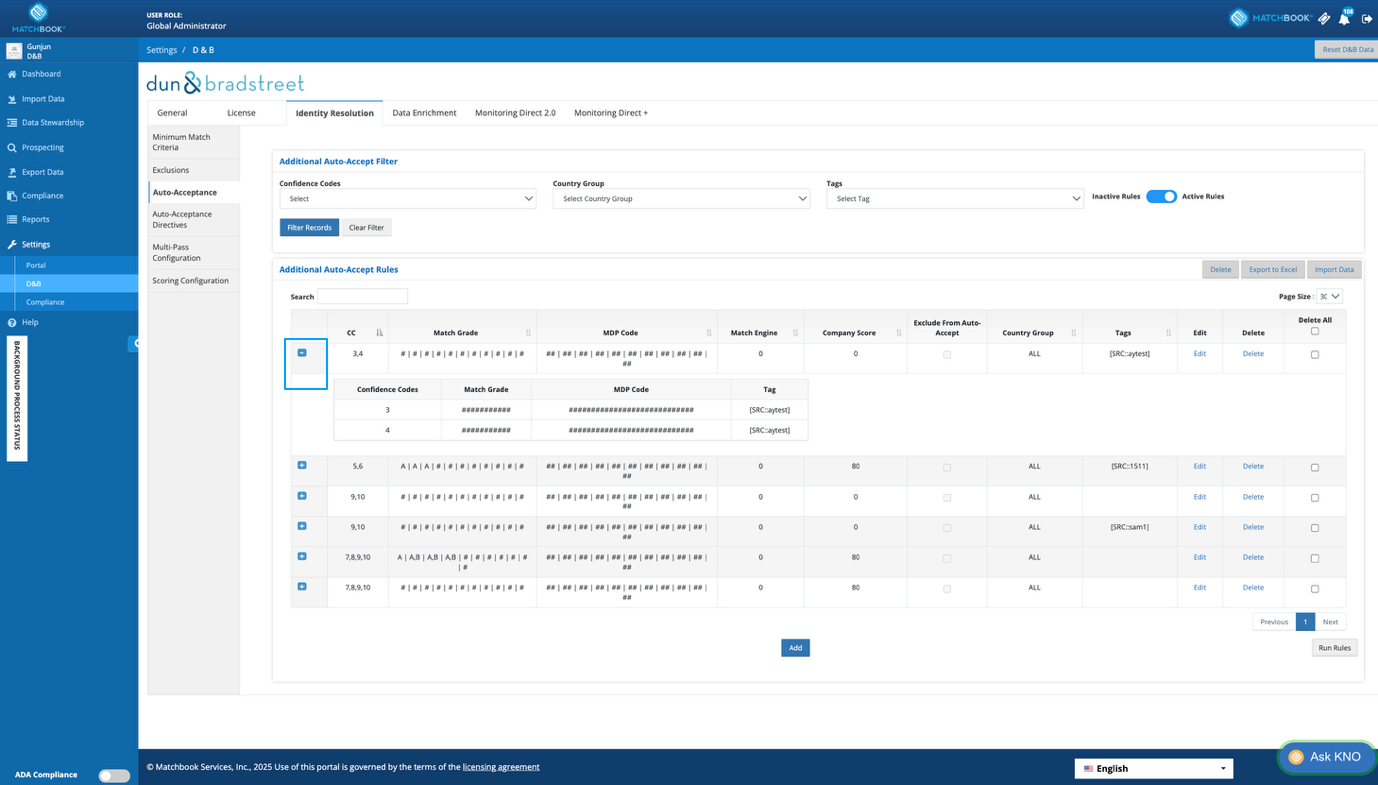
View Details: Expand the rule to view details.
Run Rules: Manually trigger rule execution
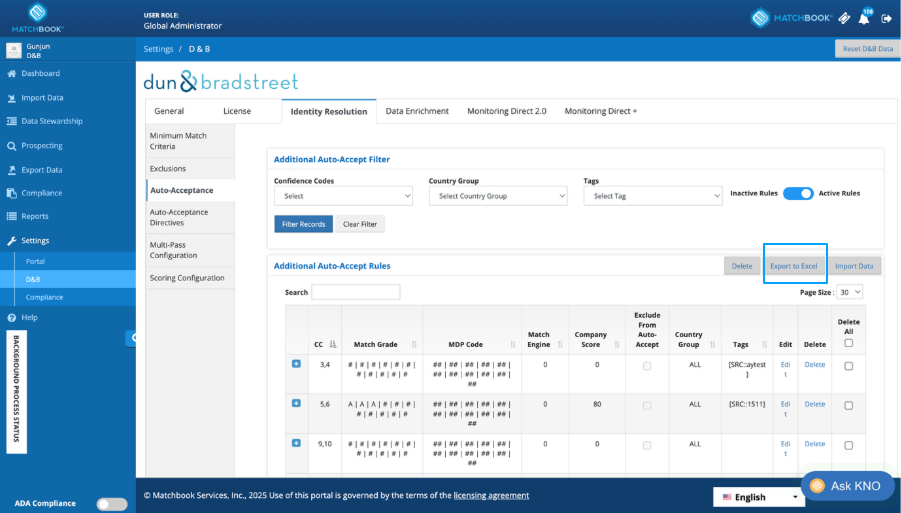
Export to Excel: Download current rules
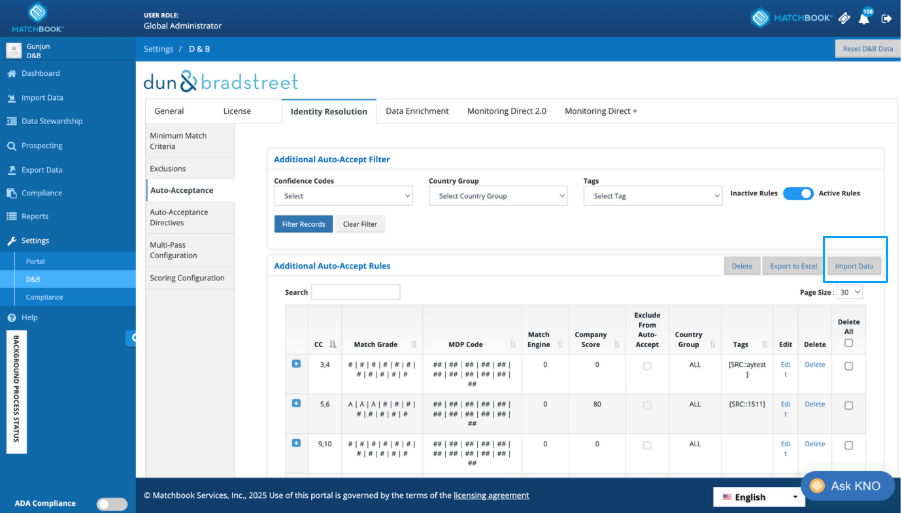
Import Data: Upload rules in bulk
Use pagination controls at the bottom to navigate across large rule sets.
Creating and Editing Auto-Acceptance Rules
The Auto-Acceptance interface allows platform administrators to define rules that automatically approve potential matches based on configurable criteria such as confidence codes, match grades, tags, and more.
Rules can be added using the Add button or edited using the Edit link from the rules table. Both actions open the Auto-Acceptance Rule configuration modal.
Add New Auto Acceptance Rule
Edit Auto Acceptance Rule
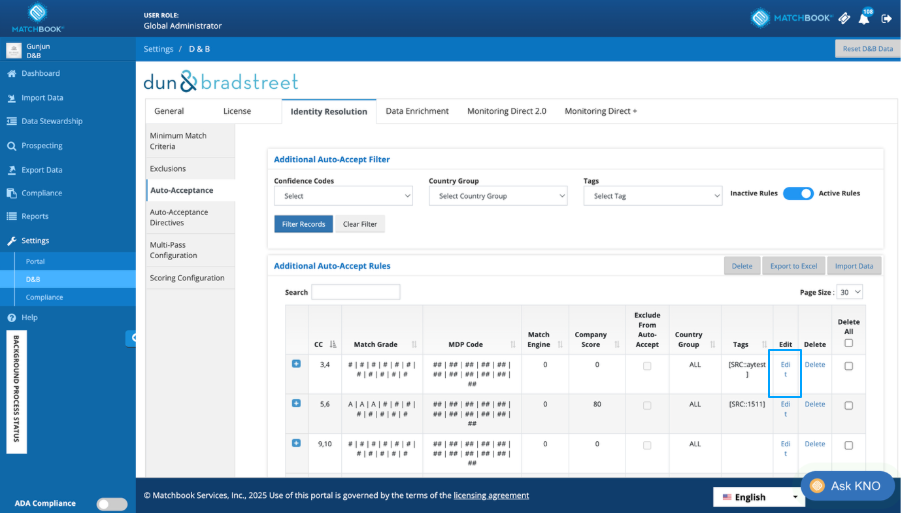
Required Fields
Fields marked with an asterisk (*) are mandatory. A rule cannot be saved unless all required fields are populated.
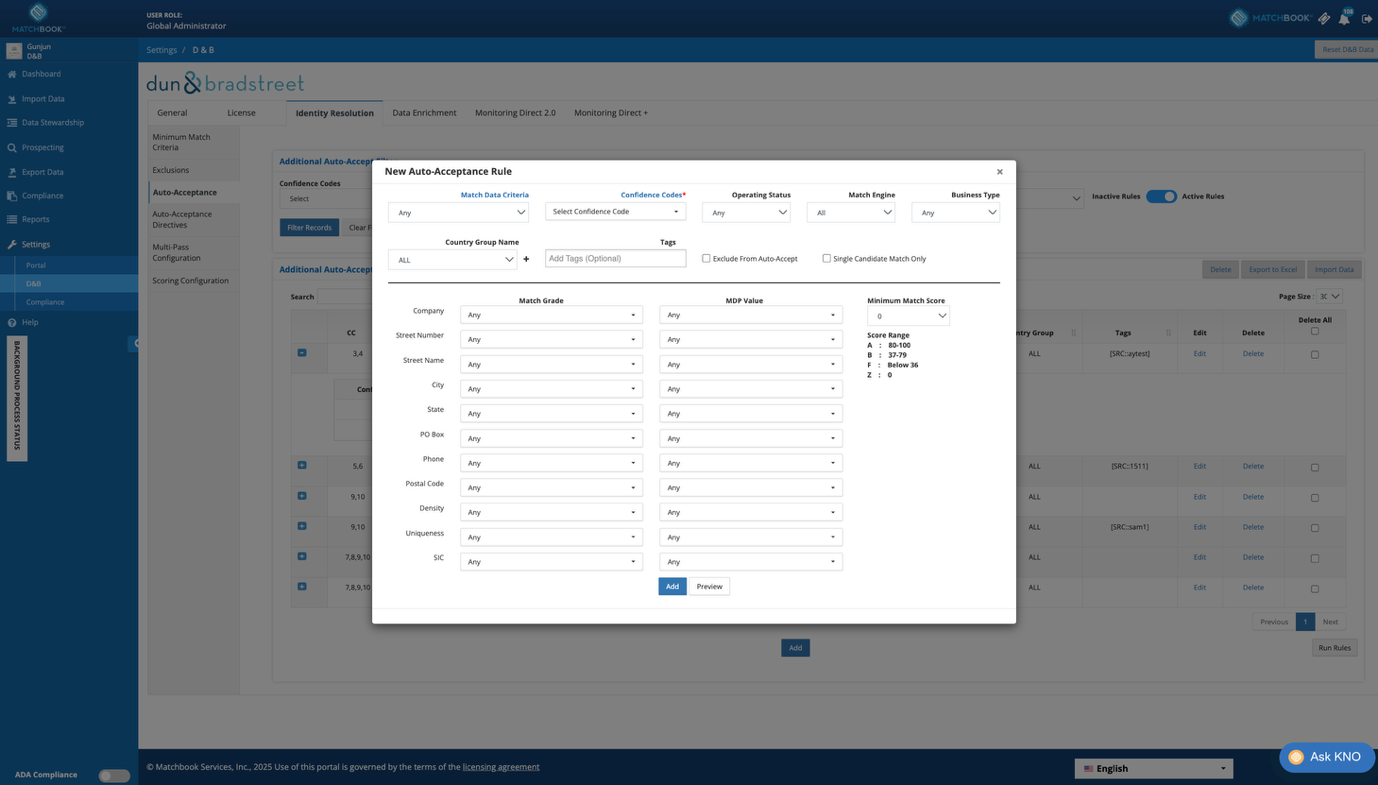
Mandatory Fields:
Confidence Code(s) (*)
Country Group Name (*)
Tags (*)
Available Fields and Descriptions
Fields |
Description |
|---|---|
Confidence Code(s) |
Specifies which match confidence levels the rule applies to (e.g., 3, 4) |
Country Group Name |
Defines geographic applicability of the rule. Must match an existing group defined in master configuration |
Tags |
Business-specific labels used to segment rule applicability |
Operating Status |
Filters based on active/inactive status of matched entities |
Match Engine |
Optionally restricts rule to specific match engine(s) |
Business Type |
Filters by standalone vs. linked business records |
Exclude From Auto-Accept |
Marks the rule to be skipped during auto-accept evaluation |
Single Candidate Match Only |
Enables rule only when a single candidate exists |
Minimum Match Score |
Numeric threshold for company score (0–100). Affects auto-accept eligibility |
Match Data Criteria (Company, Street, City, etc.) |
Dropdown fields under Match Grade and MDP Value allow detailed control over which components contribute to a rule’s applicability. All are optional and default to Any |
Score Ranges: A = 80-100, B = 37-79, F = Below 36, Z = 0
Actions
Add: Saves a new rule
Update: Saves changes to an existing rule
Preview: Displays a rule summary for validation before saving
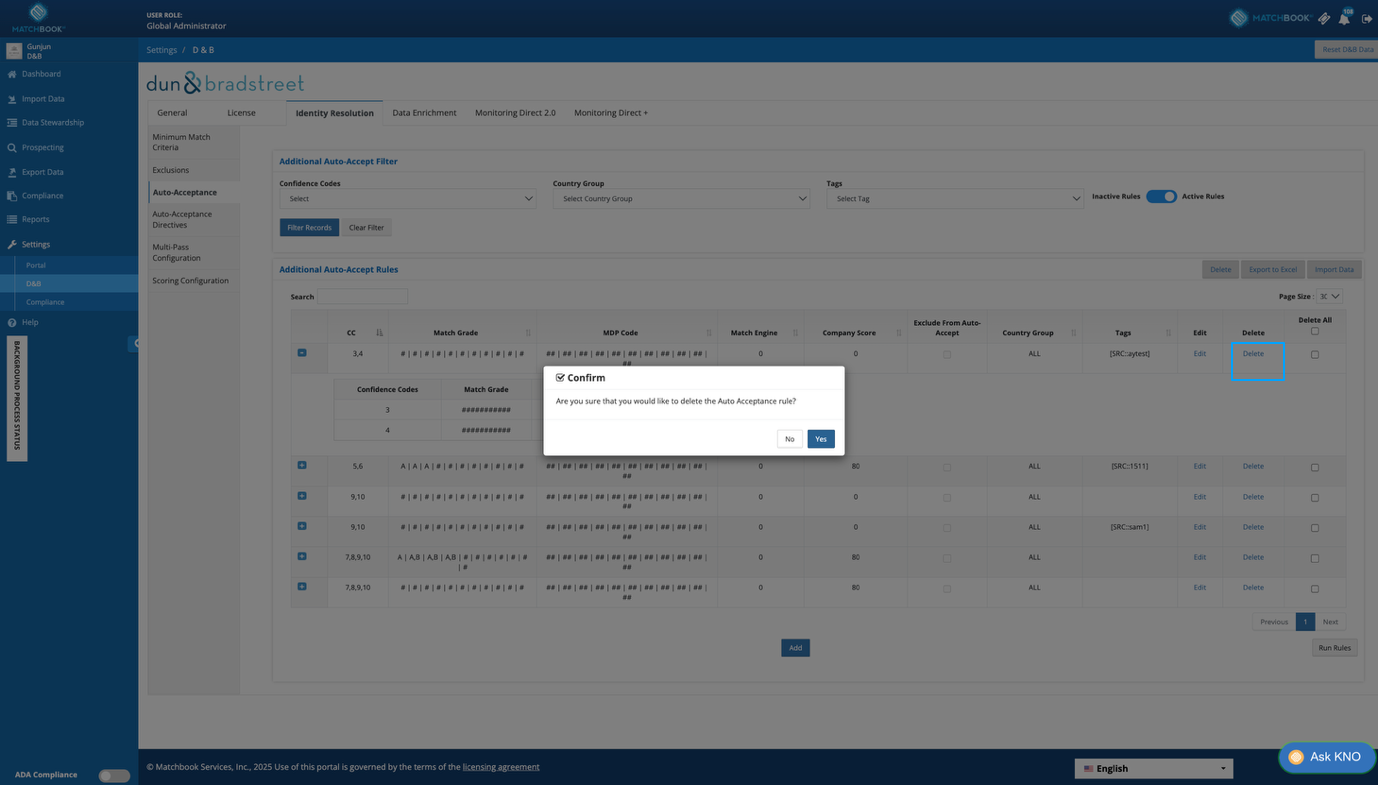
Delete Rule
Click on the delete option provided in each row to delete the respective auto acceptance rule.
Auto-Acceptance Directives
Auto-acceptance directives help the system decide which match candidates should be considered before applying detailed rules or scoring. These directives act like filters and preferences- helping you control what kinds of records get auto-accepted, and in what order.
You can access this section via:
Settings → D&B → Identity Resolution → Auto-Acceptance Directives
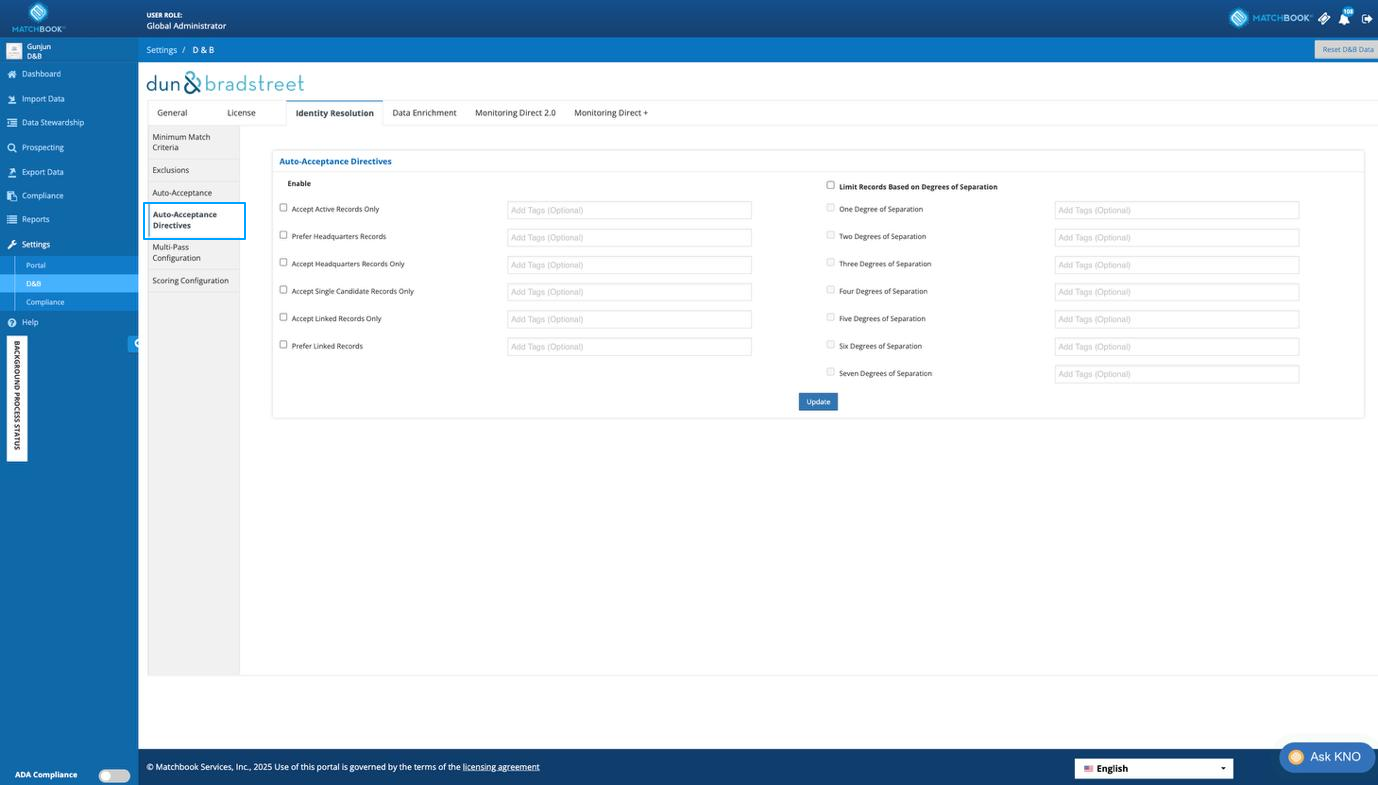
Types of Auto Acceptance Directives
Users can set global directives (apply to everything) or tag-specific ones (for certain types of data or use cases). These settings live in your configuration and can be adjusted by your admin or implementation team.
There are two kinds, both types of directives are applied early in the match process, before scoring or rule matching.
Limiting Directives: These are strict rules. If a candidate doesn’t meet them, it’s excluded from auto-acceptance.
Preference Directives: These are softer rules. They don’t exclude candidates, but they influence which ones get picked first.
Limiting Directives
These must all be true for a candidate to qualify:
Active Records Only: Only accepts candidates that are marked “active.”
Single Candidate Only: The system will only auto-accept if there’s just one candidate to choose from.
Headquarters Only: Only headquarters records will be considered.
Linked Records Only: Accepts only records that are part of a linked entity chain.
If a candidate doesn’t meet one of these? It’s out.
Preference Directives
These shift the ranking to help the best record rise to the top:
Prefer Headquarters: HQ records stay at the top. Non-HQ records are moved down the list.
Prefer Linked Records: Linked records are ranked higher than standalone ones.
Multi-Pass Configuration
Multi-Pass Configuration enables advanced match verification by requiring multiple lookup steps to pass before a candidate is considered for auto-acceptance. This ensures higher match confidence, especially in complex or low-confidence data environments.
Access this via:
Settings → D&B → Identity Resolution → Multi-Pass Configuration
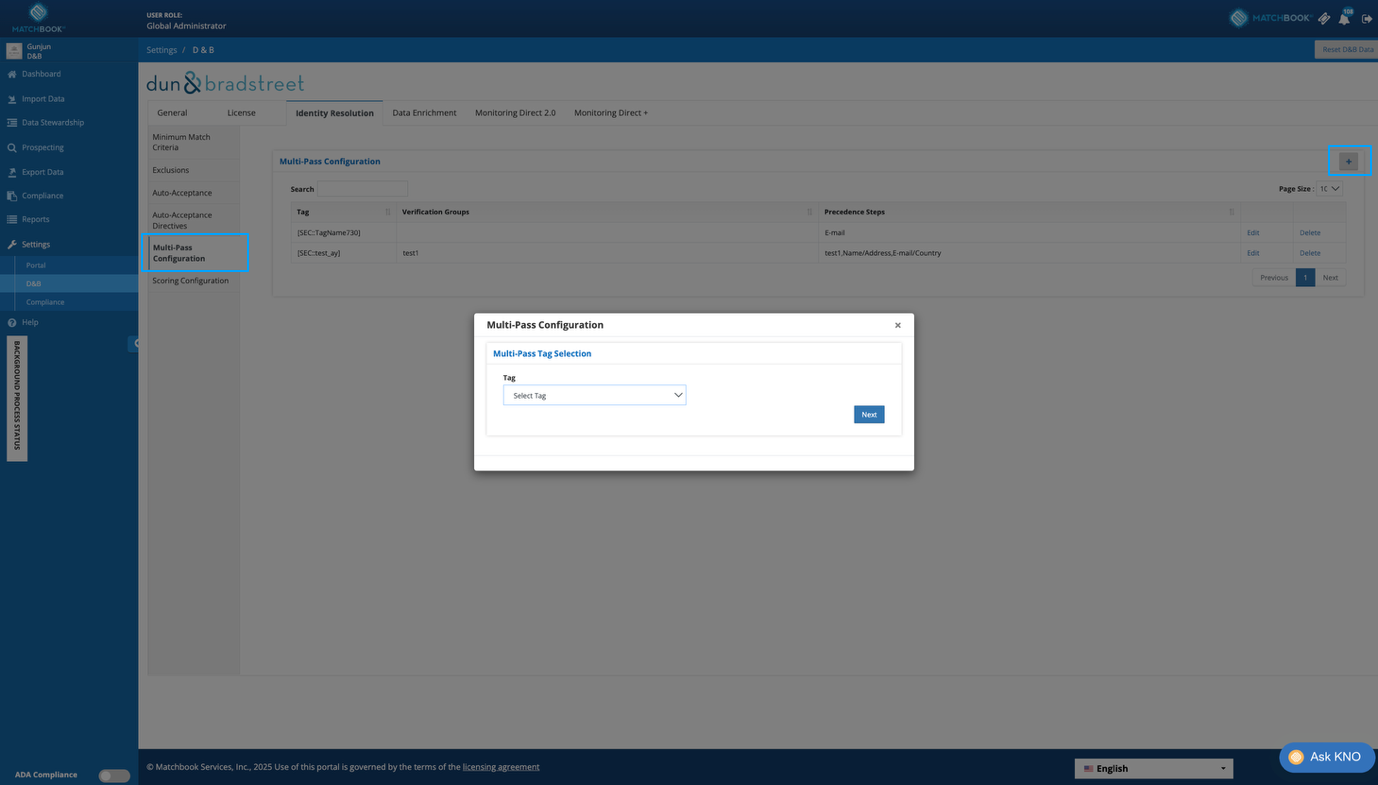
Multi-Pass logic is tag-specific. Each configuration defines a set of Verification Groups and Precedence Steps for a selected tag. This ensures that records with that tag only qualify for auto-acceptance if all required passes succeed.
Key fields
Term |
Description |
|---|---|
Tag |
Contextual identifier used to scope multi-pass logic. |
Verification Groups |
Grouped lookup types (e.g., Name, Address, Email) that must all succeed as a unit. |
Precedence Steps |
Ordered sequence of verification steps. A step passes only if all its group lookups succeed. All steps must pass for the rule to qualify. |
How It Works
Select a Tag using the + icon or from the list.
Assign Verification Groups that define what data must be validated together.
Define Precedence Steps in sequence- each using a comma-separated list of lookups (e.g., Name, Address, then Email).
Save the configuration.
The order of precedence steps determines evaluation flow. If any step fails, the record will not be auto-accepted- even if other steps pass.
Actions
Action |
Description |
|---|---|
Edit |
Modify verification groups or steps for a tag |
Delete |
Remove multi-pass logic for a tag |
Search |
Filter configurations by tag name |
Scoring Configuration
Scoring Configuration defines how match candidates are ranked during the auto-acceptance process. By assigning weights to specific attributes, users can influence which candidate is prioritized when multiple matches qualify under a rule.
Scoring can be configured globally or scoped to specific Tags.
You can access this section via:
Settings → D&B → Identity Resolution → Scoring Configuration
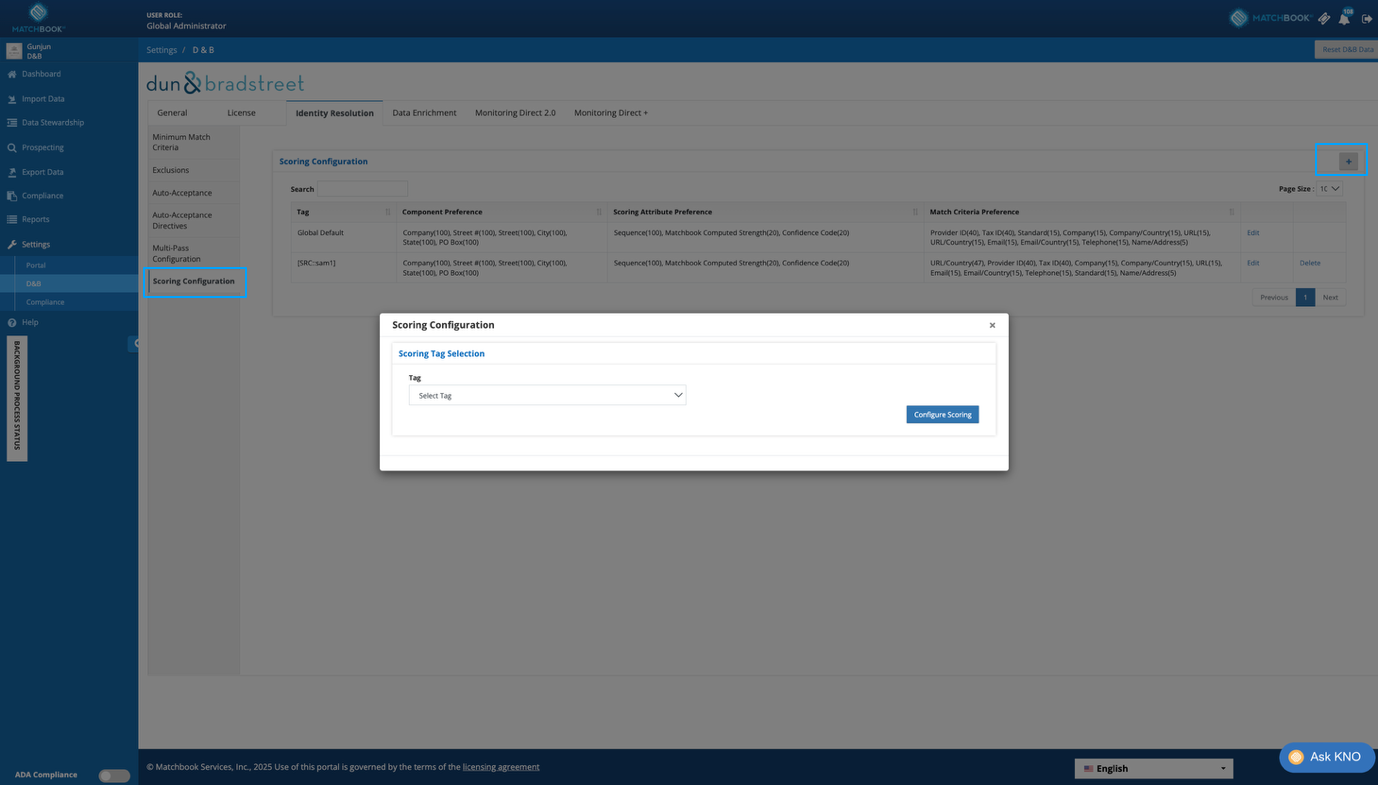
Overview
Each scoring configuration consists of three weighted preference areas:
Area |
Purpose |
|---|---|
Component Preference |
Weights assigned to match components such as Company, Street, City, PO Box, etc. |
Scoring Attribute Preference |
Prioritizes computed attributes such as Confidence Code, Matchbook Strength, Sequence Number |
Match Criteria Preference |
Weights for specific provider-based or field-based criteria like Email, URL, Tax ID, etc. |
Configuration Steps
Click the + icon to open the Scoring Tag Selection modal.
Select a Tag from the dropdown to apply tag-specific scoring.
Click Configure Scoring to define weighted preferences for that tag.
Adjust values for each category as needed.
Save changes to apply.
If no tag is selected, a Global Default scoring model will be applied during rule evaluation.
Table Fields
Column |
Description |
|---|---|
Tag |
Target context for the scoring logic |
Component Preference |
Human-readable breakdown of component weights |
Scoring Attribute Preference |
Computed match-level score weights |
Match Criteria Preference |
Custom logic tied to fields or data source attributes |
Edit / Delete |
Modify or remove configuration |